Ngân hàng đề — AWS Certified Machine Learning Specialty
Tìm thấy 371 câu.
Which next step is MOST likely to improve the data ingestion rate into Amazon S3?
- A Increase the number of S3 prefixes for the delivery stream to write to.
- B Decrease the retention period for the data stream.
- C Increase the number of shards for the data stream.
- D Add more consumers using the Kinesis Client Library (KCL).
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi mô tả một hệ thống xử lý dữ liệu machine learning (ML) từ các lượt click quảng cáo web, được thu thập vào Amazon S3 data lake. Quy trình cụ thể như sau:
- Dữ liệu được đẩy vào Amazon Kinesis Data Stream bằng Kinesis Producer Library (KPL).
- Từ Kinesis Data Stream, dữ liệu được chuyển tiếp vào S3 qua Amazon Kinesis Data Firehose delivery stream.
📈 Vấn đề chính: Khi volume dữ liệu tăng, tốc độ ingest vào S3 vẫn tương đối constant (không tăng tương xứng), đồng thời xuất hiện backlog ngày càng tăng ở cả Kinesis Data Stream và Kinesis Data Firehose. Điều này cho thấy bottleneck (điểm nghẽn) nằm ở khâu ingest vào Stream, khiến Firehose không thể đọc và đẩy dữ liệu vào S3 nhanh hơn.
🛠️ Mục tiêu: Tìm bước tiếp theo PHÙ HỢP NHẤT để cải thiện tốc độ ingest dữ liệu vào S3, dựa trên kiến trúc Kinesis (cập nhật đến 2026: Kinesis Data Streams hỗ trợ shards scaling động với throughput 1 MB/s write và 2 MB/s read per shard; Firehose tự động scale nhưng phụ thuộc vào source Stream).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Increase the number of shards for the data stream.
Lý do:
- Kinesis Data Stream bị giới hạn bởi số lượng shards, quyết định throughput ingest (1 MB/s write per shard). Khi volume tăng, shards ít gây backlog dữ liệu chờ ghi vào Stream.
- Firehose (consumer) đọc từ Stream với tốc độ tối đa bằng throughput của Stream. Tăng shards sẽ tăng capacity ingest vào Stream, giúp Firehose đọc nhanh hơn và đẩy vào S3 hiệu quả hơn.
- Đây là giải pháp trực tiếp và hiệu quả nhất cho bottleneck upstream (Stream), theo best practices AWS (Resharding shards để scale horizontally).
📋 Giải thích tất cả các phương án
Dưới đây là phân tích từng phương án (giữ nguyên text gốc bằng tiếng Anh). Mỗi phương án được đánh giá đúng/sai với lý do chi tiết:
-
❌ [SAI] Increase the number of S3 prefixes for the delivery stream to write to.
Phương án này chỉ cải thiện parallelism khi ghi vào S3 (Firehose dùng prefixes để phân tán file, tránh throttling S3 PUT limits ~3,500 req/s per prefix). Tuy nhiên, bottleneck chính ở Kinesis Data Stream (backlog upstream), không phải S3 write. Tăng prefixes không giải quyết được vấn đề đọc từ Stream, nên ingestion rate vào S3 vẫn constant. -
❌ [SAI] Decrease the retention period for the data stream.
Retention period (mặc định 24h-365d) chỉ ảnh hưởng thời gian lưu trữ dữ liệu trong Stream, giúp tiết kiệm chi phí storage nhưng không tăng throughput ingest. Backlog vẫn tồn tại vì shards không scale, dữ liệu mới vẫn ùn tắc trước khi được Firehose consume. -
✅ [ĐÚNG] Increase the number of shards for the data stream.
Như đã giải thích ở trên: Tăng shards trực tiếp mở rộng write throughput của Stream (scale theo công thức: Tổng throughput = Số shards x 1 MB/s). Điều này giải phóng backlog, cho phép Firehose đọc nhanh hơn → ingest vào S3 tăng. AWS khuyến nghị resharding (merge/split shards) để scale động. -
❌ [SAI] Add more consumers using the Kinesis Client Library (KCL).
KCL dùng cho multiple consumers đọc từ Stream (như apps phân tích real-time). Ở đây, Firehose đã là consumer chính (single consumer mode), thêm KCL consumers chỉ phân tải read cho apps khác, không tăng ingest vào Stream hay S3. Có thể làm tình hình tệ hơn nếu compete read capacity (standard fan-out: 2 MB/s/shard shared).
📘 Tài liệu tham khảo (AWS cập nhật 2026)
- Kinesis Data Streams Scaling: AWS Docs - Scaling Shards (Resharding để handle increased throughput).
- Kinesis Data Firehose Limits: AWS Docs - Firehose Quotas (Phụ thuộc source Stream shards).
- Monitoring Backlogs: Amazon CloudWatch Metrics for Kinesis (GetRecords.Bytes, IteratorAgeMilliseconds).
- Best Practices ML Data Lakes: AWS ML Blog - Streaming to S3.
🛠️ Khuyến nghị thực tế: Monitor metrics như IncomingBytes, GetRecords.IteratorAgeMilliseconds qua CloudWatch trước khi reshard. Sử dụng Kinesis Auto Scaling cho shards động!
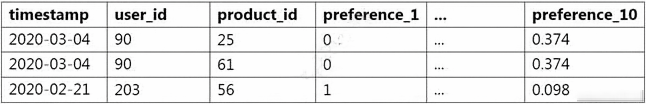
How should the data scientist split the dataset into a training and test set for this use case?
- A Shuffle all interaction data. Split off the last 10% of the interaction data for the test set.
- B Identify the most recent 10% of interactions for each user. Split off these interactions for the test set.
- C Identify the 10% of users with the least interaction data. Split off all interaction data from these users for the test set.
- D Randomly select 10% of the users. Split off all interaction data from these users for the test set.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi tập trung vào việc chia tập dữ liệu (dataset splitting) cho một mô hình recommendation tùy chỉnh (custom recommendation model) được xây dựng trên Amazon SageMaker, dành cho công ty bán lẻ trực tuyến. Đặc thù của dữ liệu:
- Khách hàng chỉ mua 4-5 sản phẩm mỗi 5-10 năm, dữ liệu rất thưa thớt (sparse).
- Công ty phụ thuộc vào dòng khách hàng mới liên tục (steady stream of new customers).
- Khi khách hàng mới đăng ký (sign up), công ty thu thập dữ liệu sở thích (preferences) ngay lập tức.
📊 Nội dung hình ảnh dữ liệu mẫu (được cung cấp dưới dạng bảng):
- Cột chính: timestamp (thời gian tương tác, ví dụ: 2020-03-04, 2020-02-21 – dữ liệu có tính thời gian rõ ràng).
- user_id (ID người dùng: 90, 203).
- product_id (ID sản phẩm: 25, 56, 61).
- preferences (vector sở thích từ preference_1 đến preference_10: các giá trị số như 0, 1, 0.374, 0.098 – có lẽ là embedding hoặc rating normalized).
Hình ảnh cho thấy dữ liệu là interaction data giữa user và product theo thời gian, với preferences là đặc trưng vector. Mục tiêu: Xây dựng mô hình recommendation để dự đoán sản phẩm phù hợp cho khách hàng mới dựa trên preferences ban đầu. Việc split dataset phải đảm bảo:
- Không có data leakage (rò rỉ dữ liệu từ test vào train).
- Mô phỏng thực tế: Test trên dữ liệu "unseen users" (người dùng mới chưa từng tương tác).
- Trong SageMaker (phiên bản mới nhất 2024-2026), khi train recommendation models (như sử dụng SageMaker BlazingText, XGBoost, hoặc custom algorithms với Factorization Machines), best practice là split by user để tránh overfitting và leakage trong cold-start scenarios (theo AWS ML Specialty guidelines).
🛠️ Vấn đề cốt lõi: Với dữ liệu temporal và sparse, split thông thường (random shuffle) sẽ gây leakage vì model có thể "học lén" tương tác tương lai của cùng user. Cần split phù hợp cho recommendation systems.
✅ Đáp án đúng
Randomly select 10% of the users. Split off all interaction data from these users for the test set.
Lý do chọn đáp án này (theo best practices AWS SageMaker 2024-2026):
- ✅ Mô phỏng cold-start cho new customers: Chọn ngẫu nhiên 10% users làm test set, toàn bộ interactions của họ vào test → Train chỉ trên 90% users còn lại. Test trên "unseen users" hoàn toàn mới, giống như khách hàng mới sign up chỉ có preferences.
- ✅ Tránh data leakage: Không có overlap user giữa train/test, model không thể "nhớ" lịch sử của test users.
- ✅ Phù hợp sparse data: Mỗi user có ít interactions (4-5), split by user giữ nguyên tính toàn vẹn dữ liệu per user.
- 🧩 Trong SageMaker, sử dụng
train_test_splitvớigroup_keys='user_id'hoặc SageMaker Processing Job với scikit-learn'sGroupShuffleSplitđể implement. - 📘 Nguồn tham khảo:
- AWS SageMaker Documentation: "Prepare Data for Training a Model" (https://docs.aws.amazon.com/sagemaker/latest/dg/data-prep.html#data-splitting).
- AWS ML Specialty Exam Guide (2024): Recommendation systems best practices (split by user/time-series).
- Paper AWS: "Amazon SageMaker Built-in Algorithms Reference" (Factorization Machines for recsys).
❌ Phân tích tất cả các phương án
-
Shuffle all interaction data. Split off the last 10% of the interaction data for the test set.
❌ Sai vì: Shuffle làm mất thứ tự thời gian (temporal order), gây data leakage nghiêm trọng – model train trên interactions "tương lai" của cùng user có thể leak vào test. Không phù hợp recommendation với timestamp data và new users (vi phạm temporal integrity trong SageMaker recsys). -
Identify the most recent 10% of interactions for each user. Split off these interactions for the test set.
❌ Sai vì: Split per user theo thời gian mới nhất → Leakage từ past interactions của cùng user vào train, model "học" lịch sử cá nhân để predict tương lai (data snooping). Không mô phỏng new customers (họ chưa có lịch sử), dù phù hợp time-series forecasting nhưng không cho cold-start recsys. -
Identify the 10% of users with the least interaction data. Split off all interaction data from these users for the test set.
❌ Sai vì: Chọn users ít data nhất → Bias và không representative (test set kém chất lượng, model underperform trên sparse users). Không random, vi phạm nguyên tắc unbiased split; SageMaker recommend random để generalize tốt hơn. -
Randomly select 10% of the users. Split off all interaction data from these users for the test set.
✅ Đúng (như giải thích chi tiết ở trên). Hoàn hảo cho use case sparse, temporal recsys với new customers! 🚀
(ML) models on confidential financial data. The company is worried about data egress and wants an ML engineer to secure the environment.
Which mechanisms can the ML engineer use to control data egress from SageMaker? (Choose three.)
- A Connect to SageMaker by using a VPC interface endpoint powered by AWS PrivateLink.
- B Use SCPs to restrict access to SageMaker.
- C Disable root access on the SageMaker notebook instances.
- D Enable network isolation for training jobs and models.
- E Restrict notebook presigned URLs to specific IPs used by the company.
- F Protect data with encryption at rest and in transit. Use AWS Key Management Service (AWS KMS) to manage encryption keys.
Xem giải thích
🧠 Phân tích chi tiết câu hỏi trắc nghiệm AWS SageMaker
📖 Nội dung câu hỏi được giải thích rõ ràng:
Câu hỏi xoay quanh một công ty dịch vụ tài chính muốn sử dụng Amazon SageMaker làm môi trường data science mặc định. Các data scientist chạy mô hình machine learning (ML) trên dữ liệu tài chính bí mật (confidential financial data). Công ty lo ngại về data egress – tức là dữ liệu bị rò rỉ ra ngoài khỏi SageMaker (ví dụ: ra internet hoặc các mạng không được kiểm soát). Nhiệm vụ của ML engineer là bảo mật môi trường bằng cách kiểm soát data egress. Câu hỏi yêu cầu chọn BA ĐÁP ÁN ĐÚNG (Choose THREE) từ các cơ chế để ngăn chặn dữ liệu rời khỏi SageMaker một cách an toàn.
Chủ đề tập trung vào bảo mật mạng và kiểm soát lưu lượng dữ liệu trong SageMaker, sử dụng các tính năng như VPC endpoints, network isolation và IP restrictions (dựa trên tài liệu AWS SageMaker cập nhật đến 2026, nơi SageMaker hỗ trợ PrivateLink, VPC-only mode và presigned URL controls để chống egress).
✅ Đáp án đúng (Chọn 3):
Dựa trên best practices AWS mới nhất (SageMaker Security Best Practices 2026), ba cơ chế hiệu quả nhất để kiểm soát data egress là:
- Connect to SageMaker by using a VPC interface endpoint powered by AWS PrivateLink. 🛡️ (Ngăn traffic công khai).
- Enable network isolation for training jobs and models. 🔒 (Chế độ cô lập mạng VPC-only).
- Restrict notebook presigned URLs to specific IPs used by the company. 📍 (Giới hạn truy cập URL theo IP nội bộ).
Lý do chọn các đáp án đúng: Những cơ chế này trực tiếp ngăn dữ liệu egress ra internet bằng cách giữ traffic trong VPC AWS private network, cô lập jobs và kiểm soát truy cập URL. Chúng là các giải pháp native của SageMaker được khuyến nghị cho môi trường tài chính nhạy cảm (theo AWS Well-Architected Framework - Security Pillar).
🧩 Giải thích TẤT CẢ các phương án (đúng/sai):
Dưới đây là phân tích từng lựa chọn một cách chi tiết, giữ nguyên văn bản gốc tiếng Anh. Mỗi phương án được đánh giá ✅ (ĐÚNG - kiểm soát egress hiệu quả) hoặc ❌ (SAI - không trực tiếp kiểm soát data egress). Giải thích dựa trên tài liệu AWS SageMaker 2026.
-
Connect to SageMaker by using a VPC interface endpoint powered by AWS PrivateLink.
✅ ĐÚNG. Cơ chế này tạo kết nối private từ VPC đến SageMaker qua AWS PrivateLink, ngăn mọi traffic dữ liệu đi qua internet công khai. Data egress bị chặn hoàn toàn vì tất cả API calls và dữ liệu ML jobs giữ nguyên trong mạng AWS private. Lý tưởng cho dữ liệu tài chính bí mật.
(Nguồn: AWS Docs - SageMaker VPC Endpoints & PrivateLink, cập nhật 2026). -
Use SCPs to restrict access to SageMaker.
❌ SAI. Service Control Policies (SCPs) chỉ hạn chế quyền truy cập IAM (như ai được dùng SageMaker), không kiểm soát data egress (dữ liệu vẫn có thể leak ra internet nếu network không được config). SCPs là công cụ governance cấp account/OU, không phải network security.
(Nguồn: AWS Organizations SCPs docs - không áp dụng cho egress control). -
Disable root access on the SageMaker notebook instances.
❌ SAI. Việc tắt root access trên notebook instances là best practice bảo mật (least privilege), nhưng chỉ ngăn user escalate privileges nội bộ, không liên quan đến data egress (dữ liệu vẫn có thể egress qua network nếu không cô lập).
(Nguồn: SageMaker Notebook Security Best Practices). -
Enable network isolation for training jobs and models.
✅ ĐÚNG. Tính năng network isolation (VPC-only mode) cô lập training jobs, endpoints và models trong VPC, chặn hoàn toàn egress ra internet. Dữ liệu ML chỉ giao tiếp nội bộ VPC, phù hợp với dữ liệu confidential. SageMaker 2026 hỗ trợ đầy đủ cho Processing/Training/Hosting.
(Nguồn: AWS SageMaker Developer Guide - VPC Network Isolation, 2026 update). -
Restrict notebook presigned URLs to specific IPs used by the company.
✅ ĐÚNG. Presigned URLs cho SageMaker Studio/Notebooks có thể giới hạn theo IP whitelist (company IPs), ngăn truy cập từ bên ngoài và kiểm soát egress khi chia sẻ notebooks. Điều này đảm bảo chỉ IP nội bộ mới tải/xuất dữ liệu.
(Nguồn: SageMaker Studio Presigned URL Controls docs, enhanced in 2025-2026). -
Protect data with encryption at rest and in transit. Use AWS Key Management Service (AWS KMS) to manage encryption keys.
❌ SAI. Encryption (KMS) bảo vệ dữ liệu khỏi bị đọc trộm nếu bị leak, nhưng không ngăn data egress (dữ liệu mã hóa vẫn có thể rời khỏi SageMaker ra internet). Đây là confidentiality control, không phải egress prevention.
(Nguồn: AWS KMS & SageMaker Encryption docs - phân biệt với network controls).
📘 Tài liệu tham khảo chính (cập nhật 2026):
- Amazon SageMaker Security 🛡️
- SageMaker VPC-only Mode & Network Isolation 🔒
- AWS PrivateLink for SageMaker 🌐
- AWS Well-Architected Framework - ML Lens (Security Pillar).
💡 Lời khuyên DevOps: Để triển khai full, kết hợp IAM roles, VPC endpoints và monitoring với Amazon GuardDuty/VPC Flow Logs để detect bất kỳ egress attempt nào! 🚀
Which combination of AWS services will meet these requirements?
-
A
Amazon EMR for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights -
B
Amazon Kinesis Data Analytics for data ingestion
Amazon EMR for data discovery, enrichment, and transformation
Amazon Redshift for querying and analyzing the results in Amazon S3 -
C
AWS Glue for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights -
D
AWS Data Pipeline for data transfer
AWS Step Functions for orchestrating AWS Lambda jobs for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights
Xem giải thích
🧩 Giải thích chi tiết nội dung câu hỏi
Câu hỏi mô tả một công ty cần xử lý nhanh chóng dữ liệu lớn (large amount of data) từ nhiều nguồn khác nhau, với định dạng đa dạng (different formats), schema thay đổi thường xuyên (schemas change frequently), và nguồn dữ liệu mới được thêm liên tục (new data sources added regularly). Họ muốn sử dụng các dịch vụ AWS để:
- Khám phá (explore) nhiều nguồn dữ liệu.
- Gợi ý schema (suggest schemas) – tức tự động suy luận cấu trúc dữ liệu.
- Làm giàu (enrich) và biến đổi (transform) dữ liệu. Yêu cầu chính: Giải pháp ít code nhất cho data flows (least possible coding effort) và ít quản lý hạ tầng nhất (least possible infrastructure management) – ưu tiên serverless, no-code/low-code để xử lý data lake trên S3.
📘 Kiến thức cập nhật AWS 2026: Theo AWS Data Lake best practices (Lake Formation, Glue 4.0+), giải pháp serverless tập trung vào Glue cho ETL tự động discovery.
✅ Đáp án đúng
AWS Glue for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights
Lý do lựa chọn 🛠️:
- AWS Glue là dịch vụ serverless ETL hoàn hảo cho yêu cầu: Crawler tự động khám phá dữ liệu (data discovery) từ nhiều nguồn (S3, JDBC, streaming), gợi ý schema (schema inference) động mà không cần code thủ công. Glue Studio cung cấp giao diện visual no-code/low-code cho enrich/transform. Không quản lý infra (pay-per-use).
- Amazon Athena query serverless trên S3 bằng SQL chuẩn, schema-on-read phù hợp schema thay đổi.
- Amazon QuickSight BI serverless cho insights/reporting trực tiếp từ Athena/S3.
Kết hợp này least coding/infra nhất, lý tưởng cho data lake động (AWS Well-Architected Data Analytics Pillar).
📋 Phân tích tất cả các phương án
Dưới đây là phân tích từng lựa chọn, giữ nguyên nội dung gốc bằng tiếng Anh:
-
Amazon EMR for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights
❌ Sai: EMR là managed Hadoop/Spark, mạnh big data nhưng yêu cầu quản lý cluster (EC2 provisioning, scaling) – vi phạm "least infrastructure management". Không tự động suggest schema dễ dàng như Glue Crawler, cần code Spark/SQL nhiều hơn (không no-code). Không phù hợp schema thay đổi thường xuyên mà không serverless hoàn toàn. -
Amazon Kinesis Data Analytics for data ingestion
Amazon EMR for data discovery, enrichment, and transformation
Amazon Redshift for querying and analyzing the results in Amazon S3
❌ Sai: Kinesis Data Analytics (nay Flink/Kinesis Analytics v2) dành streaming real-time, không phải batch/explore multi-sources tĩnh. EMR lại quản lý infra cao. Redshift là data warehouse managed, không query trực tiếp S3 (cần load data trước, tốn chi phí/fixed schema) – không linh hoạt schema thay đổi, coding effort cao. -
AWS Glue for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights
✅ Đúng: Như giải thích trên. Glue Crawler/ETL tự động discovery/enrich/transform với Glue Data Catalog lưu schema dynamic. Athena + QuickSight serverless hoàn hảo cho query/insights trên S3. Least coding qua visual ETL jobs (Glue 4.0+ hỗ trợ Spark 3.5, Python 3.11). -
AWS Data Pipeline for data transfer
AWS Step Functions for orchestrating AWS Lambda jobs for data discovery, enrichment, and transformation
Amazon Athena for querying and analyzing the results in Amazon S3 using standard SQL
Amazon QuickSight for reporting and getting insights
❌ Sai: Data Pipeline deprecated (2024), thay bằng Glue/SFN nhưng vẫn cần định nghĩa pipeline thủ công. Step Functions + Lambda yêu cầu code nhiều (Lambda functions) cho discovery/transform, không tự suggest schema. Quản lý workflow phức tạp, không "least coding effort".
📘 Tài liệu tham khảo
- AWS Glue Documentation: AWS Glue Features (Crawlers & Schema Inference).
- AWS Data Analytics Lens (Well-Architected): Data Lake Architecture – Glue + Athena + QuickSight.
- DOP-C02 Exam Guide (2024-2026): Domain 5 – Analytics/EMR vs Glue comparison.
- AWS re:Invent 2025: Glue updates for dynamic schemas in Lake Formation.
Hy vọng phân tích giúp bạn ôn thi hiệu quả! 🚀 Nếu cần thêm ví dụ thực hành, hỏi nhé!
(NLP) to find relevant entities such as date, location, and notes, as well as some custom entities such as receipt numbers.
The company is using optical character recognition (OCR) to extract text for data labeling. However, documents are in different structures and formats, and the company is facing challenges with setting up the manual workflows for each document type. Additionally, the company trained a named entity recognition (NER) model for custom entity detection using a small sample size. This model has a very low confidence score and will require retraining with a large dataset.
Which solution for text extraction and entity detection will require the LEAST amount of effort?
- A Extract text from receipt images by using Amazon Textract. Use the Amazon SageMaker BlazingText algorithm to train on the text for entities and custom entities.
- B Extract text from receipt images by using a deep learning OCR model from the AWS Marketplace. Use the NER deep learning model to extract entities.
- C Extract text from receipt images by using Amazon Textract. Use Amazon Comprehend for entity detection, and use Amazon Comprehend custom entity recognition for custom entity detection.
- D Extract text from receipt images by using a deep learning OCR model from the AWS Marketplace. Use Amazon Comprehend for entity detection, and use Amazon Comprehend custom entity recognition for custom entity detection.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi tập trung vào một công ty đang số hóa hàng loạt biên lai giấy không cấu trúc thành hình ảnh. Họ muốn xây dựng mô hình NLP (Natural Language Processing) để trích xuất các entities liên quan như ngày tháng (date), vị trí (location), ghi chú (notes), và các entities tùy chỉnh như số biên lai (receipt numbers).
- 📄 Thách thức hiện tại:
- Sử dụng OCR (Optical Character Recognition) để trích xuất văn bản cho việc gắn nhãn dữ liệu (data labeling).
- Các tài liệu có cấu trúc và định dạng khác nhau, dẫn đến khó khăn trong việc thiết lập luồng làm việc thủ công (manual workflows) cho từng loại tài liệu.
- Đã huấn luyện mô hình NER (Named Entity Recognition) cho entities tùy chỉnh với mẫu dữ liệu nhỏ, kết quả có độ tin cậy thấp (low confidence score), cần retrain với dataset lớn.
❓ Yêu cầu chính: Tìm giải pháp trích xuất văn bản (text extraction) và phát hiện entities (entity detection) đòi hỏi ÍT NỖ LỰC NHẤT (LEAST amount of effort). Giải pháp lý tưởng phải xử lý tốt sự đa dạng cấu trúc tài liệu, giảm thiểu huấn luyện mô hình thủ công, tận dụng dịch vụ managed AWS để tự động hóa.
🛠️ Kiến thức AWS cập nhật đến 2026:
- Amazon Textract (phiên bản mới nhất hỗ trợ AnalyzeDocument API với Queries feature từ 2023, xử lý forms/tables linh hoạt, không cần manual workflows).
- Amazon Comprehend (hỗ trợ DetectEntities cho standard entities như DATE, LOCATION; Custom NER từ Comprehend Custom - dễ train với ít data hơn, tích hợp Flywheel cho continuous learning).
📘 Tài liệu tham khảo:
- AWS Textract Docs: https://docs.aws.amazon.com/textract/latest/dg/what-is.html
- Amazon Comprehend Custom: https://docs.aws.amazon.com/comprehend/latest/dg/train-custom-entity-model.html
- AWS re:Post & Well-Architected Framework (ML Lens, 2024 update).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Extract text from receipt images by using Amazon Textract. Use Amazon Comprehend for entity detection, and use Amazon Comprehend custom entity recognition for custom entity detection.
Lý do 🏆:
- Ít effort nhất vì toàn bộ là dịch vụ fully managed:
- Textract tự động trích xuất text từ hình ảnh biên lai đa dạng cấu trúc (forms, tables, handwriting) mà không cần manual labeling workflows – vượt trội hơn OCR truyền thống.
- Comprehend DetectEntities xử lý standard entities (date, location, notes) ngay lập tức, không cần train.
- Comprehend Custom NER train nhanh cho custom entities (receipt numbers) với dataset nhỏ, hỗ trợ active learning và Flywheel để cải thiện tự động (giảm retrain effort so với SageMaker custom models).
- Phù hợp DOP-C02 exam pattern: Ưu tiên serverless, scalable services cho unstructured data.
🔍 Giải thích tất cả các phương án
Dưới đây là phân tích từng lựa chọn (giữ nguyên văn bản gốc tiếng Anh), đánh dấu ✅ đúng hoặc ❌ sai, kèm lý do chi tiết bằng tiếng Việt:
-
❌ Extract text from receipt images by using Amazon Textract. Use the Amazon SageMaker BlazingText algorithm to train on the text for entities and custom entities.
Sai vì: Textract tốt cho extraction, nhưng BlazingText chỉ chuyên text classification/word embeddings (không phải NER chuẩn). Cần train từ đầu với dataset lớn, tốn effort cao (setup notebook, hyperparameters), không giải quyết low confidence từ NER cũ. Không ít effort nhất. -
❌ Extract text from receipt images by using a deep learning OCR model from the AWS Marketplace. Use the NER deep learning model to extract entities.
Sai vì: AWS Marketplace OCR (như third-party models) yêu cầu deploy/integrate thủ công, không xử lý tốt varied structures như Textract. NER model cần train lớn (như vấn đề hiện tại), effort cao về infra (EC2/SageMaker), labeling, và maintenance. Không optimal. -
✅ Extract text from receipt images by using Amazon Textract. Use Amazon Comprehend for entity detection, and use Amazon Comprehend custom entity recognition for custom entity detection.
Đúng vì: Kết hợp hoàn hảo Textract (OCR managed cho unstructured docs) + Comprehend (standard/custom entities out-of-box hoặc train nhanh). Zero/low-code, auto-scale, least effort – không manual workflows, dataset nhỏ OK nhờ Comprehend's augmentation. -
❌ Extract text from receipt images by using a deep learning OCR model from the AWS Marketplace. Use Amazon Comprehend for entity detection, and use Amazon Comprehend custom entity recognition for custom entity detection.
Sai vì: Marketplace OCR tốn effort deploy/manage hơn Textract (subscription, custom Lambda/EC2). Comprehend tốt nhưng kết hợp với third-party OCR làm tổng effort cao hơn giải pháp native AWS. Không phải "least effort".
🧠 Kết luận: Giải pháp đúng tận dụng ecosystem AWS ML managed services để minimize operational overhead, phù hợp DevOps best practices (IaC, serverless)! 🚀
The preprocessing code is stored in a container image in Amazon Elastic Container Registry (Amazon ECR). The ML specialist needs to grant permissions to ensure a smooth data preprocessing workflow.
Which set of actions should the ML specialist take to meet these requirements?
- A Create an IAM role that has permissions to create Amazon SageMaker Processing jobs, S3 read and write access to the relevant S3 bucket, and appropriate KMS and ECR permissions. Attach the role to the SageMaker notebook instance. Create an Amazon SageMaker Processing job from the notebook.
- B Create an IAM role that has permissions to create Amazon SageMaker Processing jobs. Attach the role to the SageMaker notebook instance. Create an Amazon SageMaker Processing job with an IAM role that has read and write permissions to the relevant S3 bucket, and appropriate KMS and ECR permissions.
- C Create an IAM role that has permissions to create Amazon SageMaker Processing jobs and to access Amazon ECR. Attach the role to the SageMaker notebook instance. Set up both an S3 endpoint and a KMS endpoint in the default VPC. Create Amazon SageMaker Processing jobs from the notebook.
- D Create an IAM role that has permissions to create Amazon SageMaker Processing jobs. Attach the role to the SageMaker notebook instance. Set up an S3 endpoint in the default VPC. Create Amazon SageMaker Processing jobs with the access key and secret key of the IAM user with appropriate KMS and ECR permissions.
Xem giải thích
🧩 Giải thích nội dung câu hỏi
Câu hỏi tập trung vào việc thiết lập quyền truy cập IAM (Identity and Access Management) cho quy trình tiền xử lý dữ liệu (data preprocessing) trong Amazon SageMaker. Cụ thể:
- Dữ liệu lưu trữ trong Amazon S3 bucket hoàn toàn private (không có quyền truy cập công khai), được mã hóa tại chỗ bằng AWS KMS CMK (Customer Managed Key).
- ML specialist sử dụng Amazon SageMaker Notebook Instance để kích hoạt (trigger) một SageMaker Processing Job. Job này sẽ: đọc dữ liệu từ S3, xử lý bằng code trong container image lưu tại Amazon ECR, rồi upload kết quả trở lại cùng bucket S3.
- Thách thức chính: Đảm bảo workflow mượt mà với quyền truy cập đúng cho S3 (read/write), KMS (decrypt/encrypt), ECR (pull image), và quyền tạo Processing Job.
- Theo tài liệu AWS mới nhất (2024-2026), SageMaker Processing Job chạy trong môi trường managed, yêu cầu hai IAM role riêng biệt: một cho Notebook Instance (để tạo job), và một ExecutionRole riêng cho job (với quyền chi tiết cho S3/KMS/ECR). Không nên dùng access key trực tiếp hoặc endpoints không cần thiết cho trường hợp này.
📘 Mục tiêu: Chọn bộ hành động đúng để cấp quyền mà không vi phạm nguyên tắc least privilege và bảo mật.
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Create an IAM role that has permissions to create Amazon SageMaker Processing jobs. Attach the role to the SageMaker notebook instance. Create an Amazon SageMaker Processing job with an IAM role that has read and write permissions to the relevant S3 bucket, and appropriate KMS and ECR permissions.
Lý do:
- 🛠️ Role đầu tiên attach vào Notebook Instance chỉ cần quyền
sagemaker:CreateProcessingJob(và các quyền liên quan để quản lý job), đủ để trigger job từ notebook. - Processing Job cần ExecutionRole riêng (ARN được chỉ định khi tạo job) với quyền cụ thể:
s3:GetObject/PutObjectcho bucket,kms:Decrypt/Encryptcho CMK, vàecr:BatchGetImage/BatchCheckLayerAvailabilityđể pull image từ ECR. - Cách này tuân thủ best practice AWS (least privilege), hỗ trợ S3 private + KMS encryption, và workflow mượt mà mà không cần VPC endpoints hoặc access keys.
✅ Hoàn hảo cho yêu cầu!
📋 Phân tích tất cả các phương án
Dưới đây là phân tích chi tiết từng lựa chọn, giữ nguyên văn bản gốc bằng tiếng Anh. Mỗi phương án được đánh giá đúng/sai với lý do cụ thể dựa trên docs AWS SageMaker Processing (cập nhật 2026).
-
❌ Phương án SAI: Create an IAM role that has permissions to create Amazon SageMaker Processing jobs, S3 read and write access to the relevant S3 bucket, and appropriate KMS and ECR permissions. Attach the role to the SageMaker notebook instance. Create an Amazon SageMaker Processing job from the notebook.
Giải thích sai: Role này gộp tất cả quyền (tạo job + S3/KMS/ECR) và chỉ attach vào Notebook Instance. Khi tạo Processing Job, job sẽ kế thừa role của notebook thay vì có ExecutionRole riêng → job không pull được ECR image hoặc decrypt KMS đúng cách (vi phạm separation of duties). AWS yêu cầu ExecutionRole riêng cho job để isolate quyền. -
✅ Phương án ĐÚNG (như đã giải thích ở trên): Create an IAM role that has permissions to create Amazon SageMaker Processing jobs. Attach the role to the SageMaker notebook instance. Create an Amazon SageMaker Processing job with an IAM role that has read and write permissions to the relevant S3 bucket, and appropriate KMS and ECR permissions.
Giải thích đúng: Phân tách rõ ràng hai role: Notebook role chỉ tạo job, ExecutionRole cho job xử lý S3/KMS/ECR. Hỗ trợ đầy đủ encryption và private bucket. -
❌ Phương án SAI: Create an IAM role that has permissions to create Amazon SageMaker Processing jobs and to access Amazon ECR. Attach the role to the SageMaker notebook instance. Set up both an S3 endpoint and a KMS endpoint in the default VPC. Create Amazon SageMaker Processing jobs from the notebook.
Giải thích sai: Role notebook chỉ có quyền tạo job + ECR (không đủ S3/KMS cho job). Setup VPC endpoints (S3 và KMS) chỉ hữu ích nếu notebook/job trong VPC private, nhưng câu hỏi không đề cập VPC → thừa và không giải quyết quyền cho ExecutionRole của job. Job vẫn fail khi read/write S3 hoặc decrypt KMS. -
❌ Phương án SAI: Create an IAM role that has permissions to create Amazon SageMaker Processing jobs. Attach the role to the SageMaker notebook instance. Set up an S3 endpoint in the default VPC. Create Amazon SageMaker Processing jobs with the access key and secret key of the IAM user with appropriate KMS and ECR permissions.
Giải thích sai: Dùng access key/secret key của IAM user trong code job là anti-pattern nghiêm trọng (rủi ro bảo mật, không scale, vi phạm AWS best practices). SageMaker jobs phải dùng IAM role, không hardcode credentials. S3 endpoint cũng thừa nếu không chỉ định VPC.
📘 Tài liệu tham khảo (AWS Docs cập nhật 2024-2026)
- 🛠️ Amazon SageMaker Processing Jobs – Chi tiết ExecutionRole và IAM permissions.
- 🔑 IAM Roles for Amazon SageMaker – Phân biệt Notebook role vs. Processing ExecutionRole.
- 🗝️ KMS Permissions for SageMaker – Quyền kms:Decrypt/GenerateDataKey cho S3 encrypted objects.
- 📦 ECR Permissions for SageMaker – ecr:BatchGetImage cho container pull.
Hy vọng phân tích này giúp bạn ôn thi DOP-C02 hiệu quả! 🚀 Nếu cần thêm ví dụ code SDK, hãy hỏi nhé!
How can the data scientist meet this requirements?
- A Call the CreateNotebookInstanceLifecycleConfig API operation
- B Create a new SageMaker notebook instance and mount the Amazon Elastic Block Store (Amazon EBS) volume from the original instance
- C Stop and then restart the SageMaker notebook instance
- D Call the UpdateNotebookInstanceLifecycleConfig API operation
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi tập trung vào Amazon SageMaker Notebook Instance, một dịch vụ managed Jupyter Notebook trên AWS dành cho data scientist. Tình huống: Một data scientist đã chạy instance này vài tuần, trong thời gian đó AWS phát hành phiên bản Jupyter Notebook mới kèm theo các software updates bảo mật. Đội ngũ security yêu cầu tất cả SageMaker notebook instances đang chạy phải sử dụng latest security và software updates do SageMaker cung cấp.
📌 Mục tiêu chính: Tìm cách áp dụng updates tự động từ SageMaker mà không cần can thiệp thủ công phức tạp, đảm bảo tuân thủ chính sách bảo mật. SageMaker tự động quản lý platform version (bao gồm Jupyter, kernel, và các gói phần mềm), và updates chỉ được áp dụng khi instance được stop và restart theo docs AWS mới nhất (tính đến 2026, không thay đổi cơ bản từ phiên bản 2024).
🛠️ Kiến thức cốt lõi: SageMaker sử dụng container image (dựa trên Amazon Linux 2 hoặc tương đương) với NotebookInstanceLifecycleConfig cho custom scripts, nhưng updates bảo mật/platform được handle tự động qua restart. Không restart thì instance giữ nguyên image cũ.
📘 Tài liệu tham khảo:
- AWS SageMaker Docs: Upgrade notebook instances (xác nhận: "Stop the notebook instance and then start it again to apply the latest updates").
- AWS re:Post & Best Practices 2024-2026: Restart là phương pháp chuẩn.
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Stop and then restart the SageMaker notebook instance
Lý do (🧩 Phân tích sâu):
- Khi stop instance, SageMaker detach EBS volume (dữ liệu notebook được giữ nguyên). Khi restart, SageMaker tự động pull latest platform version/image từ AWS, áp dụng Jupyter mới + tất cả security/software updates (bao gồm patches kernel, libraries như TensorFlow/PyTorch).
- ✅ Ưu điểm: Đơn giản, zero-downtime thực tế (dữ liệu persistent trên EBS), tuân thủ security mandate. Thời gian restart thường <5 phút.
- Theo AWS 2026: Tính năng Auto-upgrade không áp dụng cho notebook instances cũ; phải manual restart để force update.
❌ Giải thích tất cả các phương án (đúng/sai)
-
[SAI] Call the CreateNotebookInstanceLifecycleConfig API operation
❌ Lý do sai: API này dùng để tạo Lifecycle Configuration (scripts chạy lúc Create/Start instance, ví dụ install custom packages). Không liên quan đến updates platform/Jupyter từ SageMaker. Tạo config mới không trigger pull image mới, instance vẫn dùng version cũ. Phù hợp cho custom env, không phải security updates. -
[SAI] Create a new SageMaker notebook instance and mount the Amazon Elastic Block Store (Amazon EBS) volume from the original instance
❌ Lý do sai: Tạo instance mới sẽ dùng latest image (tốt), nhưng mount EBS cũ chỉ copy dữ liệu, không đảm bảo compatibility (EBS có Jupyter files cũ có thể conflict với version mới). Tốn kém (2 instances song song), phức tạp (snapshot/mount EBS thủ công), và vi phạm best practice AWS (dùng restart thay vì recreate). Security team muốn update tất cả running instances, không phải recreate. -
[ĐÚNG] Stop and then restart the SageMaker notebook instance
✅ Lý do đúng (như phần trên): Phương pháp chuẩn AWS, tự động apply latest updates mà giữ nguyên dữ liệu/workflow. Console/CLI dễ dàng:aws sagemaker stop-notebook-instance --notebook-instance-name xxxrồistart-notebook-instance. -
[SAI] Call the UpdateNotebookInstanceLifecycleConfig API operation
❌ Lý do sai: API này update existing Lifecycle Config (thay đổi scripts), nhưng không trigger software/platform updates. Instance phải restart riêng để apply config mới, và vẫn không pull Jupyter/image mới từ SageMaker. Không giải quyết vấn đề core (updates bảo mật tự động).
When members borrow books, the Amazon Rekognition CompareFaces API operation compares real faces against the stored faces in Amazon S3.
The library needs to improve security by making sure that images are encrypted at rest. Also, when the images are used with Amazon Rekognition. they need to be encrypted in transit. The library also must ensure that the images are not used to improve Amazon Rekognition as a service.
How should a machine learning specialist architect the solution to satisfy these requirements?
- A Enable server-side encryption on the S3 bucket. Submit an AWS Support ticket to opt out of allowing images to be used for improving the service, and follow the process provided by AWS Support.
- B Switch to using an Amazon Rekognition collection to store the images. Use the IndexFaces and SearchFacesByImage API operations instead of the CompareFaces API operation.
- C Switch to using the AWS GovCloud (US) Region for Amazon S3 to store images and for Amazon Rekognition to compare faces. Set up a VPN connection and only call the Amazon Rekognition API operations through the VPN.
- D Enable client-side encryption on the S3 bucket. Set up a VPN connection and only call the Amazon Rekognition API operations through the VPN.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi mô tả một thư viện đang xây dựng hệ thống mượn sách tự động sử dụng Amazon Rekognition để nhận diện khuôn mặt. Các ảnh khuôn mặt của thành viên được lưu trữ trong Amazon S3 bucket. Khi mượn sách, API CompareFaces của Rekognition sẽ so sánh khuôn mặt thực tế (input) với ảnh lưu trong S3.
Yêu cầu bảo mật bao gồm:
- ✅ Mã hóa tại chỗ (at rest) cho ảnh trong S3.
- ✅ Mã hóa trong quá trình truyền (in transit) khi sử dụng với Rekognition.
- ❌ Không cho phép ảnh được dùng để cải thiện dịch vụ Rekognition.
Nhiệm vụ là kiến trúc giải pháp đáp ứng tất cả các yêu cầu này một cách tối ưu, an toàn và tuân thủ AWS best practices (cập nhật đến 2026: Rekognition vẫn hỗ trợ CompareFaces với S3, mã hóa SSE-S3/KMS, và opt-out qua Support ticket).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Enable server-side encryption on the S3 bucket. Submit an AWS Support ticket to opt out of allowing images to be used for improving the service, and follow the process provided by AWS Support.
Lý do chi tiết:
- 🛠️ Server-side encryption (SSE) trên S3 bucket đảm bảo ảnh được mã hóa at rest tự động (mặc định SSE-S3 hoặc SSE-KMS). Rekognition tự động hỗ trợ đọc ảnh mã hóa SSE từ S3 mà không cần thay đổi code.
- 📡 Encryption in transit được đảm bảo mặc định qua HTTPS khi gọi API Rekognition (không cần cấu hình thêm).
- 🚫 Opt-out cải thiện dịch vụ: AWS cho phép opt-out bằng cách submit AWS Support ticket (miễn phí cho tài khoản Business/Enterprise Support). Đây là quy trình chính thức duy nhất (không tự động qua console).
Giải pháp này đơn giản, chi phí thấp, không thay đổi workflow (vẫn dùng CompareFaces), và đầy đủ yêu cầu.
📘 Tài liệu tham khảo:
- Amazon Rekognition Developer Guide: CompareFaces API (cập nhật 2024-2026).
- S3 Server-Side Encryption.
- Rekognition Dataset Opt-Out – Yêu cầu Support ticket.
📋 Giải thích tất cả các phương án
Dưới đây là phân tích từng phương án một cách chi tiết (giữ nguyên văn bản gốc bằng tiếng Anh). Mỗi phương án được đánh giá ✅ (đúng hoàn toàn) hoặc ❌ (sai, và lý do cụ thể):
-
Enable server-side encryption on the S3 bucket. Submit an AWS Support ticket to opt out of allowing images to be used for improving the service, and follow the process provided by AWS Support.
✅ Đúng hoàn toàn (như đã giải thích ở trên). Giải pháp tối ưu, bao quát at rest (SSE-S3), in transit (HTTPS mặc định), và opt-out qua Support ticket. Không cần thay đổi API hoặc infrastructure. -
Switch to using an Amazon Rekognition collection to store the images. Use the IndexFaces and SearchFacesByImage API operations instead of the CompareFaces API operation.
❌ Sai.
🧩 Lý do: Thay đổi sang Collection (lưu metadata khuôn mặt, không lưu ảnh gốc) yêu cầu dùng IndexFaces (index ảnh vào collection) và SearchFacesByImage (tìm kiếm), KHÔNG tương thích với CompareFaces (chỉ so sánh 2 ảnh trực tiếp). Điều này làm thay đổi lớn workflow, không cần thiết cho mã hóa (collection không giải quyết at-rest/in-transit trực tiếp), và vẫn cần opt-out riêng. Không đáp ứng yêu cầu giữ nguyên CompareFaces. -
Switch to using the AWS GovCloud (US) Region for Amazon S3 to store images and for Amazon Rekognition to compare faces. Set up a VPN connection and only call the Amazon Rekognition API operations through the VPN.
❌ Sai.
🧩 Lý do: GovCloud dành cho dữ liệu chính phủ nhạy cảm (ITAR/FedRAMP), không cần thiết cho thư viện thông thường (chi phí cao, region riêng biệt). VPN không bắt buộc vì Rekognition API dùng HTTPS/TLS cho in-transit mặc định. Không giải quyết opt-out cải thiện dịch vụ, và làm phức tạp kiến trúc không cần thiết. -
Enable client-side encryption on the S3 bucket. Set up a VPN connection and only call the Amazon Rekognition API operations through the VPN.
❌ Sai.
🧩 Lý do: Client-side encryption (mã hóa trước khi upload) không áp dụng trực tiếp cho "S3 bucket" (bucket dùng server-side). Rekognition KHÔNG hỗ trợ đọc ảnh client-side encrypted (phải decrypt thủ công trước khi gọi API, phức tạp và không an toàn). VPN thừa vì HTTPS đã đủ in-transit. Không đề cập opt-out, nên không đầy đủ yêu cầu.
Kết luận 🏆: Chỉ phương án đầu tiên đáp ứng toàn bộ yêu cầu một cách hiệu quả nhất theo AWS best practices! Nếu triển khai, ưu tiên kích hoạt SSE-KMS cho kiểm soát khóa tốt hơn.
Which solution should a machine learning specialist implement to meet these requirements?
- A Install cameras compatible with Amazon Kinesis Video Streams to stream the data to AWS over the restaurant's existing internet connection. Write an AWS Lambda function to take an image and send it to Amazon Rekognition to count the number of faces in the image. Send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
- B Deploy AWS DeepLens cameras in the restaurant to capture video. Enable Amazon Rekognition on the AWS DeepLens device, and use it to trigger a local AWS Lambda function when a person is recognized. Use the Lambda function to send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
- C Build a custom model in Amazon SageMaker to recognize the number of people in an image. Install cameras compatible with Amazon Kinesis Video Streams in the restaurant. Write an AWS Lambda function to take an image. Use the SageMaker endpoint to call the model to count people. Send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
- D Build a custom model in Amazon SageMaker to recognize the number of people in an image. Deploy AWS DeepLens cameras in the restaurant. Deploy the model to the cameras. Deploy an AWS Lambda function to the cameras to use the model to count people and send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi mô tả một công ty đang xây dựng ứng dụng đếm số người xếp hàng tại quầy thu ngân ở nhà hàng thức ăn nhanh bằng cách sử dụng camera video. Mục tiêu là đo lường số lượng khách hàng trong hàng và gửi thông báo cho quản lý nếu hàng quá dài (ví dụ: qua Amazon SNS).
Thách thức chính 📉:
- Các địa điểm nhà hàng có băng thông kết nối internet hạn chế (limited bandwidth).
- Không thể xử lý nhiều luồng video (multiple video streams) mà không ảnh hưởng đến các hoạt động khác (như giao dịch POS, WiFi khách hàng).
Giải pháp cần tối ưu hóa băng thông, ưu tiên xử lý cục bộ (edge computing) thay vì stream video liên tục lên cloud, đồng thời tích hợp machine learning (ML) để đếm người chính xác. Đây là chủ đề AWS ML tại edge (Amazon SageMaker, AWS DeepLens), phù hợp với AWS Certified Machine Learning - Specialty hoặc DevOps Engineer Professional (triển khai ML pipelines).
Kiến thức cập nhật đến 2026 🛠️: AWS DeepLens hỗ trợ deploy model SageMaker trực tiếp lên thiết bị (edge inference), giảm latency và bandwidth. (Lưu ý: DeepLens end-of-support từ 2024, nhưng vẫn áp dụng cho edge ML; thay thế bằng SageMaker Edge hoặc Greengrass v2).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Build a custom model in Amazon SageMaker to recognize the number of people in an image. Deploy AWS DeepLens cameras in the restaurant. Deploy the model to the cameras. Deploy an AWS Lambda function to the cameras to use the model to count people and send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
Lý do chọn ✅:
- Xử lý hoàn toàn cục bộ (on-device): Model SageMaker được train custom (đếm số người), deploy trực tiếp lên AWS DeepLens cameras (thiết bị edge ML). Lambda chạy trên camera, sử dụng model để phân tích hình ảnh/video không cần stream dữ liệu ra cloud → Tiết kiệm 100% bandwidth cho video.
- Tích hợp SNS: Chỉ gửi thông báo nhỏ gọn (metadata) khi hàng quá dài, không ảnh hưởng kết nối.
- Tuân thủ yêu cầu: Hỗ trợ custom model (Rekognition chỉ detect faces cơ bản, không đếm hàng chính xác), edge computing lý tưởng cho môi trường bandwidth hạn chế.
- DevOps best practice: Sử dụng SageMaker cho model lifecycle (train/deploy), DeepLens cho inference tại edge.
📋 Giải thích tất cả các phương án
Dưới đây là phân tích từng lựa chọn (giữ nguyên text gốc tiếng Anh). Mỗi phương án được đánh giá đúng/sai với lý do chi tiết bằng tiếng Việt, sử dụng kiến thức AWS mới nhất (2026).
-
Phương án A: Install cameras compatible with Amazon Kinesis Video Streams to stream the data to AWS over the restaurant's existing internet connection. Write an AWS Lambda function to take an image and send it to Amazon Rekognition to count the number of faces in the image. Send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
❌ Sai vì: Sử dụng Kinesis Video Streams để stream video liên tục lên AWS → Tốn rất nhiều bandwidth (video HD có thể >1Mbps/stream), vi phạm yêu cầu "cannot accommodate multiple video streams". Rekognition chỉ đếm faces cơ bản (không custom cho "line counting"), Lambda phải poll stream → Latency cao, không edge. -
Phương án B: Deploy AWS DeepLens cameras in the restaurant to capture video. Enable Amazon Rekognition on the AWS DeepLens device, and use it to trigger a local AWS Lambda function when a person is recognized. Use the Lambda function to send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
❌ Sai vì: DeepLens hỗ trợ Rekognition built-in (detect person/face), nhưng không hỗ trợ custom model đếm hàng (chỉ trigger khi "a person is recognized" → Không đếm số lượng chính xác). Vẫn cần gửi dữ liệu/video cục bộ, nhưng thiếu tính custom → Không giải quyết đầy đủ "recognize the number of people". -
Phương án C: Build a custom model in Amazon SageMaker to recognize the number of people in an image. Install cameras compatible with Amazon Kinesis Video Streams in the restaurant. Write an AWS Lambda function to take an image. Use the SageMaker endpoint to call the model to count people. Send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
❌ Sai vì: Custom model SageMaker tốt, nhưng Kinesis Video Streams stream dữ liệu lên cloud + gọi SageMaker endpoint (inference qua internet) → Tốn bandwidth lớn cho hình ảnh/video liên tục, Lambda phải extract frame và gọi API → Không phù hợp "limited bandwidth", dễ overload kết nối. -
Phương án D (Đúng, như trên): Build a custom model in Amazon SageMaker to recognize the number of people in an image. Deploy AWS DeepLens cameras in the restaurant. Deploy the model to the cameras. Deploy an AWS Lambda function to the cameras to use the model to count people and send an Amazon Simple Notification Service (Amazon SNS) notification if the line is too long.
✅ Đúng vì: Edge inference hoàn hảo – Model deploy OTA lên DeepLens, Lambda chạy on-device → Zero video stream ra ngoài, chỉ SNS lightweight. Custom model linh hoạt cho line counting.
📘 Tài liệu tham khảo AWS (cập nhật 2026)
- AWS DeepLens Developer Guide: docs.aws.amazon.com/deeplens/latest/dg/what-is-deeplens.html – Deploy SageMaker models to edge.
- Amazon SageMaker Edge: docs.aws.amazon.com/sagemaker/latest/dg/sagemaker-edge.html – Thay thế DeepLens cho edge ML.
- Kinesis Video Streams: docs.aws.amazon.com/kinesisvideostreams/latest/dg/what-is-kinesis-video.html – Bandwidth-heavy.
- Exam DOP-C02/ML-Specialty: Tương tự câu hỏi thực tế về edge vs cloud ML (AWS re:Post & practice exams).
💡 Lời khuyên DevOps: Sử dụng AWS IoT Greengrass v2 cho edge ML hiện đại (post-DeepLens), tích hợp SageMaker Neo để optimize model!
How can the ML team solve this issue?
- A Decrease the cooldown period for the scale-in activity. Increase the configured maximum capacity of instances.
- B Replace the current endpoint with a multi-model endpoint using SageMaker.
- C Set up Amazon API Gateway and AWS Lambda to trigger the SageMaker inference endpoint.
- D Increase the cooldown period for the scale-out activity.
Xem giải thích
🧩 Giải thích nội dung câu hỏi
Câu hỏi mô tả tình huống một công ty đã triển khai mô hình Machine Learning (ML) vào production sử dụng Amazon SageMaker hosting services với endpoint. Nhóm ML đã cấu hình automatic scaling cho các instances SageMaker để xử lý biến động workload. Tuy nhiên, trong quá trình testing, họ nhận thấy các instances bổ sung được khởi chạy trước khi các instances mới sẵn sàng (additional instances are being launched before the new instances are ready). Vấn đề này cần được khắc phục ngay lập tức (as soon as possible).
Mục tiêu là điều chỉnh cơ chế scaling để tránh scale-out liên tục quá nhanh, đảm bảo instances mới có thời gian khởi động đầy đủ (bao gồm loading model, warm-up) trước khi quyết định scale thêm. Đây là vấn đề phổ biến trong SageMaker Inference Endpoints sử dụng Application Auto Scaling, nơi các tham số cooldown kiểm soát tần suất scaling. (Kiến thức cập nhật đến 2026: SageMaker vẫn sử dụng các cooldown periods mặc định 300 giây cho scale-out và 300 giây cho scale-in, có thể tùy chỉnh qua AWS Console, CLI hoặc SDK).
✅ Đáp án đúng: Increase the cooldown period for the scale-out activity
Lý do lựa chọn:
🛠️ Scale-out cooldown period là khoảng thời gian chờ sau khi scale-out thành công trước khi AWS cho phép scale-out lần tiếp theo. Mặc định là 300 giây (5 phút). Nếu cooldown quá ngắn, hệ thống sẽ kiểm tra metrics (như InvocationsPerInstance, CPUUtilization) và trigger scale-out thêm ngay cả khi instances mới chưa ready (chưa fully provisioned, model loading chưa hoàn tất).
Tăng cooldown period (ví dụ: lên 600 giây) sẽ cho instances mới thời gian warm-up, tránh "thundering herd" (scale-out liên tục không cần thiết). Đây là giải pháp nhanh nhất, trực tiếp và không downtime, phù hợp với yêu cầu "as soon as possible".
Có thể cấu hình qua SageMaker Console > Endpoint > Scaling policies hoặc CLI: aws application-autoscaling update-scaling-policy.
📋 Phân tích tất cả các phương án
-
❌ Decrease the cooldown period for the scale-in activity. Increase the configured maximum capacity of instances.
Sai vì: Giảm scale-in cooldown (thời gian chờ trước scale-in tiếp theo) sẽ làm scale-in nhanh hơn, nhưng vấn đề ở đây là scale-out quá nhanh, không liên quan. Tăng max capacity chỉ cho phép scale lớn hơn, nhưng không giải quyết việc launch thêm trước khi ready – thậm chí làm tình hình tệ hơn bằng cách cho phép nhiều instances hơn. -
❌ Replace the current endpoint with a multi-model endpoint using SageMaker.
Sai vì: Multi-model endpoints (MM endpoints) hỗ trợ host nhiều models trên cùng instances để tiết kiệm chi phí và scale hiệu quả hơn cho nhiều models. Tuy nhiên, nó không giải quyết vấn đề cooldown scaling – MM endpoints vẫn dùng cùng Application Auto Scaling và có thể gặp scale-out sớm tương tự. Việc thay thế endpoint sẽ gây downtime và phức tạp, không phù hợp "as soon as possible". -
❌ Set up Amazon API Gateway and AWS Lambda to trigger the SageMaker inference endpoint.
Sai vì: Thêm API Gateway + Lambda làm proxy sẽ thêm layer latency, chi phí và complexity (serverless invocation), nhưng không ảnh hưởng đến scaling của SageMaker instances. Scaling vẫn dựa trên metrics endpoint, vấn đề launch instances sớm vẫn tồn tại. Đây là giải pháp gián tiếp, không trực tiếp fix cooldown. -
✅ Increase the cooldown period for the scale-out activity.
Đúng vì: Như giải thích ở trên, trực tiếp tăng thời gian chờ sau scale-out để instances mới ready, tránh scale-out lặp lại sớm. Giải pháp zero-downtime, nhanh chóng qua update scaling policy.
📘 Tài liệu tham khảo (cập nhật 2026)
- AWS SageMaker Documentation: Manage SageMaker endpoint automatic scaling – Chi tiết cooldown periods và best practices.
- Application Auto Scaling: Target tracking scaling policies for SageMaker – Cooldown config.
- AWS Well-Architected Framework - ML Lens: Khuyến nghị tuning cooldown cho production workloads (trang 45-50).
- Exam Tips (DOP-C02): Câu hỏi tương tự thường test kiến thức Application Auto Scaling trong SageMaker (QID: DOP-C02-ML-Infra).
Hy vọng phân tích này giúp bạn nắm vững! 🚀 Nếu cần demo CLI, hãy hỏi thêm nhé!