Ngân hàng đề — Google Cloud Associate Cloud Engineer
Tìm thấy 449 câu.
- A 1. Use nslookup to get the IP address for storage.googleapis.com. 2. Negotiate with the security team to be able to give a public IP address to the servers. 3. Only allow egress traffic from those servers to the IP addresses for storage.googleapis.com.
- B 1. Using Cloud VPN, create a VPN tunnel to a Virtual Private Cloud (VPC) in Google Cloud. 2. In this VPC, create a Compute Engine instance and install the Squid proxy server on this instance. 3. Configure your servers to use that instance as a proxy to access Cloud Storage.
- C 1. Use Migrate for Compute Engine (formerly known as Velostrata) to migrate those servers to Compute Engine. 2. Create an internal load balancer (ILB) that uses storage.googleapis.com as backend. 3. Configure your new instances to use this ILB as proxy.
- D 1. Using Cloud VPN or Interconnect, create a tunnel to a VPC in Google Cloud. 2. Use Cloud Router to create a custom route advertisement for 199.36.153.4/30. Announce that network to your on-premises network through the VPN tunnel. 3. In your on-premises network, configure your DNS server to resolve *.googleapis.com as a CNAME to restricted.googleapis.com.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi mô tả tình huống: Bạn đang chạy ứng dụng trên bare-metal servers (máy chủ vật lý không ảo hóa) tại data center riêng (on-premises). Ứng dụng cần truy cập Cloud Storage (dịch vụ lưu trữ của Google Cloud). Tuy nhiên, chính sách bảo mật cấm các server này có public IP hoặc truy cập internet. Bạn cần áp dụng thực hành được Google khuyến nghị để cung cấp quyền truy cập an toàn cho ứng dụng đến Cloud Storage mà không vi phạm chính sách.
📌 Mục tiêu chính: Kết nối on-premises với Google Cloud APIs (như Cloud Storage) qua kênh riêng tư (private connectivity), tránh internet công cộng, sử dụng IP private và DNS tùy chỉnh để resolve các endpoint như storage.googleapis.com một cách an toàn. Đây là kịch bản phổ biến cho hybrid cloud với Private Google Access và restricted.googleapis.com.
✅ Đáp án đúng
Đáp án đúng là lựa chọn cuối cùng (đã được đánh dấu [ĐÚNG]):
- Using Cloud VPN or Interconnect, create a tunnel to a VPC in Google Cloud. 2. Use Cloud Router to create a custom route advertisement for 199.36.153.4/30. Announce that network to your on-premises network through the VPN tunnel. 3. In your on-premises network, configure your DNS server to resolve *.googleapis.com as a CNAME to restricted.googleapis.com.
Lý do chọn đáp án này 🛠️:
- Đây là phương pháp được Google chính thức khuyến nghị (Google-recommended practice) để truy cập Google APIs privately từ on-premises.
- Bước 1: Sử dụng Cloud VPN hoặc Dedicated Interconnect tạo tunnel riêng tư đến VPC trong Google Cloud, đảm bảo traffic không đi qua internet.
- Bước 2: Cloud Router advertise route 199.36.153.4/30 (IP range dành riêng cho Private Google Access đến Google APIs) về on-premises qua tunnel. Server on-prem có thể route traffic đến range này mà không cần public IP/internet.
- Bước 3: Cấu hình DNS server on-premises resolve
*.googleapis.com(bao gồmstorage.googleapis.com) thành CNAME restricted.googleapis.com, buộc traffic đi qua private IP thay vì public endpoint. - Ưu điểm: An toàn tuyệt đối (không expose public IP), scalable, tuân thủ zero-trust, và hỗ trợ cập nhật đến 2026 với Private Service Connect enhancements (mặc dù câu hỏi dùng cách classic Private Google Access).
📘 Tài liệu tham khảo:
- Google Cloud Docs: Accessing Google APIs through endpoints (cập nhật 2024-2026).
- Private Google Access for on-premises.
- Cloud Router custom routes.
❌ Phân tích tất cả các phương án
Dưới đây là giải thích chi tiết từng lựa chọn, giữ nguyên nội dung gốc bằng tiếng Anh. Mỗi phương án được đánh giá đúng/sai dựa trên tính khả thi, bảo mật và tuân thủ Google best practices (dùng kiến thức mới nhất đến 2026).
-
[SAI] 1. Use nslookup to get the IP address for storage.googleapis.com. 2. Negotiate with the security team to be able to give a public IP address to the servers. 3. Only allow egress traffic from those servers to the IP addresses for storage.googleapis.com.
❌ Sai vì: Phụ thuộc vào IP public của storage.googleapis.com (có thể thay đổi bất kỳ lúc nào do Google load balancer), vi phạm chính sách "không public IP/internet". Việc negotiate public IP trái với yêu cầu bảo mật. Không scalable và không phải Google-recommended (dễ bị DDoS, IP rotation). -
[SAI] 1. Using Cloud VPN, create a VPN tunnel to a Virtual Private Cloud (VPC) in Google Cloud. 2. In this VPC, create a Compute Engine instance and install the Squid proxy server on this instance. 3. Configure your servers to use that instance as a proxy to access Cloud Storage.
❌ Sai vì: Mặc dù dùng VPN (tốt), nhưng Squid proxy trên Compute Engine là giải pháp tự chế (DIY), phức tạp quản lý, tốn kém (chạy VM liên tục), và không được Google khuyến nghị. Dễ single point of failure, không hỗ trợ Private Google Access native. Cập nhật 2026 ưu tiên Private Service Connect thay vì proxy. -
[SAI] 1. Use Migrate for Compute Engine (formerly known as Velostrata) to migrate those servers to Compute Engine. 2. Create an internal load balancer (ILB) that uses storage.googleapis.com as backend. 3. Configure your new instances to use this ILB as proxy.
❌ Sai vì: Migrate for Compute Engine dùng để di chuyển workload (không giải quyết truy cập on-prem). Internal Load Balancer (ILB) không hỗ trợ storage.googleapis.com làm backend (ILB chỉ backend với Compute Engine/ NEGs, không phải external APIs). Đây là cấu hình không khả thi, vi phạm docs Google (ILB dành cho services nội bộ VPC).
Tóm lại, chỉ đáp án đúng mới an toàn, private, và theo best practices Google! 🚀 Nếu cần demo lab, hãy hỏi thêm nhé!
- A 1. Create a Cloud Function that uses a Cloud Pub/Sub trigger on that topic. 2. Call your application on Cloud Run from the Cloud Function for every message.
- B 1. Grant the Pub/Sub Subscriber role to the service account used by Cloud Run. 2. Create a Cloud Pub/Sub subscription for that topic. 3. Make your application pull messages from that subscription.
- C 1. Create a service account. 2. Give the Cloud Run Invoker role to that service account for your Cloud Run application. 3. Create a Cloud Pub/Sub subscription that uses that service account and uses your Cloud Run application as the push endpoint.
- D 1. Deploy your application on Cloud Run on GKE with the connectivity set to Internal. 2. Create a Cloud Pub/Sub subscription for that topic. 3. In the same Google Kubernetes Engine cluster as your application, deploy a container that takes the messages and sends them to your application.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi yêu cầu triển khai một ứng dụng trên Cloud Run để xử lý các tin nhắn từ một Cloud Pub/Sub topic, đồng thời tuân thủ các thực hành được Google khuyến nghị (Google-recommended practices).
- Mục tiêu chính: Kết nối Pub/Sub với Cloud Run một cách hiệu quả, đáng tin cậy và dễ quản lý.
- Bối cảnh: Cloud Run là dịch vụ serverless chạy container, lý tưởng cho các workload không trạng thái. Pub/Sub là hệ thống messaging asynchronous. Google khuyến nghị sử dụng push subscription để Pub/Sub tự động đẩy (push) tin nhắn trực tiếp đến endpoint HTTP của Cloud Run, thay vì pull thủ công, nhằm tận dụng tính serverless (scale-to-zero) và giảm độ trễ.
- Thách thức: Cloud Run cần được kích hoạt (invoke) bởi Pub/Sub một cách an toàn qua service account, tránh các cách gián tiếp phức tạp.
📘 Tài liệu tham khảo:
- Cloud Run Documentation: Receive Pub/Sub messages (cập nhật 2024-2026).
- Pub/Sub Push Subscriptions (khuyến nghị push cho serverless như Cloud Run).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng là phương án thứ 3:
- Create a service account. 2. Give the Cloud Run Invoker role to that service account for your Cloud Run application. 3. Create a Cloud Pub/Sub subscription that uses that service account and uses your Cloud Run application as the push endpoint.
Lý do chọn 🛠️:
- Đây là cách thức được Google khuyến nghị chính thức cho việc tích hợp Pub/Sub với Cloud Run: Sử dụng push subscription để Pub/Sub đẩy tin nhắn trực tiếp đến URL endpoint của Cloud Run (như
https://your-service-xxx.a.run.app). - Bước 1-2: Tạo service account và cấp quyền Cloud Run Invoker (roles/run.invoker) đảm bảo Pub/Sub có quyền gọi (invoke) Cloud Run mà không cần IAM rộng rãi, tuân thủ nguyên tắc least privilege.
- Bước 3: Subscription push sử dụng service account này làm push endpoint, tự động scale Cloud Run theo traffic, xử lý retry/at-least-once semantics.
- Lợi ích: Đơn giản, serverless-native, chi phí thấp, độ tin cậy cao (Pub/Sub retry tự động nếu Cloud Run 5xx).
📋 Giải thích chi tiết tất cả các phương án
-
❌ Phương án 1 (Sai):
- Create a Cloud Function that uses a Cloud Pub/Sub trigger on that topic. 2. Call your application on Cloud Run from the Cloud Function for every message.
Phân tích: Cách này thêm một lớp trung gian (Cloud Function) không cần thiết, tăng độ trễ, chi phí và điểm lỗi (cold start Function). Google không khuyến nghị vì Pub/Sub có thể push trực tiếp đến Cloud Run, tránh overhead. Phù hợp hơn cho legacy hoặc logic phức tạp.
- Create a Cloud Function that uses a Cloud Pub/Sub trigger on that topic. 2. Call your application on Cloud Run from the Cloud Function for every message.
-
❌ Phương án 2 (Sai):
- Grant the Pub/Sub Subscriber role to the service account used by Cloud Run. 2. Create a Cloud Pub/Sub subscription for that topic. 3. Make your application pull messages from that subscription.
Phân tích: Pull subscription yêu cầu Cloud Run liên tục polling (pull) tin nhắn, không tận dụng scale-to-zero của serverless (Cloud Run phải chạy liên tục). Cấp quyền Subscriber (roles/pubsub.subscriber) cho service account Cloud Run là thừa và không an toàn. Google ưu tiên push để tự động hóa.
- Grant the Pub/Sub Subscriber role to the service account used by Cloud Run. 2. Create a Cloud Pub/Sub subscription for that topic. 3. Make your application pull messages from that subscription.
-
✅ Phương án 3 (Đúng):
- Create a service account. 2. Give the Cloud Run Invoker role to that service account for your Cloud Run application. 3. Create a Cloud Pub/Sub subscription that uses that service account and uses your Cloud Run application as the push endpoint.
Phân tích: Hoàn hảo khớp recommended practice. Service account với Invoker role cho phép Pub/Sub authenticate và invoke Cloud Run an toàn. Push endpoint trực tiếp, hỗ trợ HTTPS, ack/nack tự động, và dead-letter queue. Đây là blueprint chuẩn từ docs GCP (2024+).
- Create a service account. 2. Give the Cloud Run Invoker role to that service account for your Cloud Run application. 3. Create a Cloud Pub/Sub subscription that uses that service account and uses your Cloud Run application as the push endpoint.
-
❌ Phương án 4 (Sai):
- Deploy your application on Cloud Run on GKE with the connectivity set to Internal. 2. Create a Cloud Pub/Sub subscription for that topic. 3. In the same Google Kubernetes Engine cluster as your application, deploy a container that takes the messages and sends them to your application.
Phân tích: Cloud Run on GKE (nay là Knative-based, deprecated so sánh với Cloud Run fully managed). Cài connectivity Internal và thêm container proxy trong GKE tạo kiến trúc phức tạp, tốn kém (GKE cluster luôn chạy), không serverless. Google khuyến nghị Cloud Run fully managed + push, tránh GKE trừ khi cần Kubernetes nâng cao.
- Deploy your application on Cloud Run on GKE with the connectivity set to Internal. 2. Create a Cloud Pub/Sub subscription for that topic. 3. In the same Google Kubernetes Engine cluster as your application, deploy a container that takes the messages and sends them to your application.
- A Deploy the container on Cloud Run.
- B Deploy the container on Cloud Run on GKE.
- C Deploy the container on App Engine Flexible.
- D Deploy the container on GKE with cluster autoscaling and horizontal pod autoscaling enabled.
Xem giải thích
🧩 Giải thích nội dung câu hỏi
Câu hỏi yêu cầu triển khai một ứng dụng được đóng gói trong container image lên một dự án mới trên Google Cloud. Ứng dụng này phơi bày một HTTP endpoint (tức là nhận yêu cầu qua HTTP) và chỉ nhận rất ít request mỗi ngày (traffic thấp). Mục tiêu chính là giảm thiểu chi phí tối đa.
🛠️ Phân tích tình huống:
- Đây là workload container-based, serverless lý tưởng vì traffic thấp → cần dịch vụ tự động scale xuống 0 (không chạy khi idle) để tránh phí idle time.
- Không cần quản lý hạ tầng phức tạp, ưu tiên pay-per-use (chỉ trả tiền khi có request).
- Các lựa chọn đều là dịch vụ Google Cloud hỗ trợ container, nhưng phải chọn cái tối ưu chi phí nhất cho low-traffic.
✅ Đáp án đúng và lý do lựa chọn
Deploy the container on Cloud Run.
Lý do:
- Cloud Run là dịch vụ serverless container hoàn hảo cho workload HTTP low-traffic. Nó tự động scale to zero (không chạy instance khi không có request), chỉ tính phí theo số request + thời gian CPU/memory sử dụng thực tế (giây tính phí, minimum 100ms/request).
- Với "very few requests per day", chi phí gần như bằng 0 khi idle (free tier hỗ trợ 2 triệu request/tháng miễn phí đến 2026).
- Dễ deploy:
gcloud run deploy --image=..., hỗ trợ new project ngay lập tức, không cần cluster hay config phức tạp. - Theo docs Google Cloud 2026, Cloud Run là lựa chọn cost-optimized cho stateless HTTP containers với traffic sporadic.
📋 Giải thích tất cả các phương án
Dưới đây là phân tích từng lựa chọn một, giữ nguyên văn bản gốc bằng tiếng Anh. Mỗi phương án được đánh giá ✅ (đúng) hoặc ❌ (sai), kèm lý do chi tiết dựa trên kiến thức Google Cloud mới nhất (2026).
-
✅ Deploy the container on Cloud Run.
Đúng vì: Như đã giải thích ở trên. Đây là lựa chọn tối ưu chi phí nhất cho container HTTP low-traffic, scale-to-zero, pay-per-request. Không có overhead cluster hay minimum instances. Phù hợp 100% yêu cầu "minimize costs". -
❌ Deploy the container on Cloud Run on GKE.
Sai vì: Cloud Run on GKE (nay gọi Anthos Service Mesh tích hợp) chạy trên GKE cluster, luôn có chi phí cluster baseline (node pool minimum 1 node ~$20-50/tháng, ngay cả idle). Không scale-to-zero hoàn toàn như Cloud Run thuần, traffic thấp vẫn tốn kém hơn. Không khuyến nghị cho low-traffic (docs: chỉ dùng cho hybrid/multi-cloud cần GKE features). -
❌ Deploy the container on App Engine Flexible.
Sai vì: App Engine Flexible Environment hỗ trợ container nhưng luôn chạy minimum 1 instance (không scale-to-zero), dẫn đến chi phí idle cao (~$0.05/giờ/instance, ~$36/tháng ngay cả không request). Phù hợp high-traffic hơn, low-traffic sẽ lãng phí. Theo pricing 2026, không cost-effective bằng Cloud Run. -
❌ Deploy the container on GKE with cluster autoscaling and horizontal pod autoscaling enabled.
Sai vì: GKE yêu cầu cluster luôn chạy (control plane ~$0.10/giờ + node costs), cluster autoscaling chỉ scale node theo load nhưng không scale xuống 0 (minimum nodes vẫn tốn ~$10-20/tháng). HPA scale pods nhưng vẫn cần cluster active. Với "very few requests", chi phí cao gấp nhiều lần Cloud Run. Không phù hợp minimize costs.
📘 Tài liệu tham khảo
- Cloud Run Documentation (Pricing & Scaling to zero).
- Cloud Run vs. GKE Comparison (2026 update).
- Google Cloud Pricing Calculator – Test scenario: Cloud Run low-traffic ~$0/tháng.
- Associate Cloud Engineer Exam Guide (Google Cloud Skills Boost, 2026 edition): Nhấn mạnh Cloud Run cho serverless containers cost-optimized.
Hy vọng phân tích này giúp bạn ôn thi hiệu quả! 🚀 Nếu cần ví dụ deploy code, hỏi thêm nhé!
- A Link the acquired company's projects to your company's billing account.
- B Configure the acquired company's billing account and your company's billing account to export the billing data into the same BigQuery dataset.
- C Migrate the acquired company's projects into your company's GCP organization. Link the migrated projects to your company's billing account.
- D Create a new GCP organization and a new billing account. Migrate the acquired company's projects and your company's projects into the new GCP organization and link the projects to the new billing account.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi tập trung vào tình huống quản lý billing (hóa đơn thanh toán) trong Google Cloud Platform (GCP). Công ty của bạn đã có một GCP organization (tổ chức GCP) với hàng trăm projects (dự án) và một billing account (tài khoản thanh toán). Công ty vừa mua lại một công ty khác cũng có GCP organization riêng với hàng trăm projects và billing account riêng.
Mục tiêu chính:
- Consolidate (hợp nhất) tất cả chi phí GCP của cả hai tổ chức vào một hóa đơn duy nhất (single invoice).
- Thực hiện ngay từ ngày mai (as of tomorrow) – nghĩa là cần giải pháp nhanh chóng, không tốn thời gian migrate dữ liệu.
🛠️ Điểm then chốt: Trong GCP, hóa đơn được tạo dựa trên billing account, không phải organization. Mỗi project phải được liên kết (link) với một billing account để thanh toán. Giải pháp phải đảm bảo tất cả projects từ cả hai bên được gắn vào cùng một billing account để nhận invoice chung, mà không làm gián đoạn hoạt động.
📘 Tài liệu tham khảo:
- Google Cloud Billing: Manage billing accounts (cập nhật 2024-2026).
- Link a project to a billing account – Hỗ trợ link cross-organization nhanh chóng.
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Link the acquired company's projects to your company's billing account.
Lý do chi tiết:
- Đây là cách nhanh nhất và đơn giản nhất để hợp nhất hóa đơn mà không cần migrate projects giữa các organization.
- Trong GCP, bạn có quyền chuyển billing account của project sang billing account khác (cross-organization) chỉ trong vài phút qua Google Cloud Console hoặc gcloud CLI.
- Kết quả: Tất cả projects của công ty acquired sẽ được thanh toán qua billing account của bạn → Một invoice duy nhất từ ngày mai.
- ✅ Ưu điểm: Không downtime, không mất dữ liệu, tuân thủ "as of tomorrow". Đây là best practice cho M&A scenarios trong GCP (theo docs chính thức).
🧩 Giải thích chi tiết tất cả các phương án
Dưới đây là phân tích từng lựa chọn. Tôi giữ nguyên văn bản gốc bằng tiếng Anh, chỉ giải thích bằng tiếng Việt với lý do đúng/sai:
-
Link the acquired company's projects to your company's billing account.
✅ Đúng vì: Phương án này trực tiếp gắn projects của công ty acquired vào billing account hiện có của bạn. Quy trình chỉ mất vài phút (Console > Billing > Link project), hỗ trợ cross-organization. Hóa đơn sẽ hợp nhất ngay lập tức từ ngày mai mà không cần thay đổi organization hay migrate dữ liệu. Hoàn hảo cho yêu cầu "consolidate all GCP costs onto a single invoice as of tomorrow". -
Configure the acquired company's billing account and your company's billing account to export the billing data into the same BigQuery dataset.
❌ Sai vì: Việc export dữ liệu billing vào BigQuery chỉ giúp phân tích và báo cáo dữ liệu (cost analysis), không hợp nhất hóa đơn thực tế. Bạn vẫn nhận hai invoice riêng biệt từ hai billing account. BigQuery chỉ là công cụ dữ liệu, không ảnh hưởng đến thanh toán (theo Cloud Billing export to BigQuery). -
Migrate the acquired company's projects into your company's GCP organization. Link the migrated projects to your company's billing account.
❌ Sai vì: Migrate projects giữa organizations là quá trình phức tạp, tốn thời gian (có thể hàng giờ/ngày với hàng trăm projects, cần IAM permissions, resource recreation). Không đáp ứng "as of tomorrow". Dù link billing sau migrate thì cũng không cần thiết vì có thể link trực tiếp mà không migrate. -
Create a new GCP organization and a new billing account. Migrate the acquired company's projects and your company's projects into the new GCP organization and link the projects to the new billing account.
❌ Sai vì: Tạo organization/billing mới + migrate tất cả projects từ cả hai bên là cực kỳ tốn kém thời gian (có thể hàng tuần với hàng trăm projects), rủi ro cao (downtime, data loss). Không khả thi cho "as of tomorrow". Đây là giải pháp "nặng đô" không cần thiết khi chỉ cần hợp nhất billing.
🛠️ Lời khuyên thực tế: Sử dụng Cloud Billing Console để kiểm tra permissions (Billing Account User role). Nếu cần automate, dùng gcloud: gcloud beta billing projects link PROJECT_ID --billing-account=BILLING_ACCOUNT_ID. Luôn test trên project nhỏ trước! 🚀
You need a streamlined solution to grant the correct permissions to your support team, and you want to follow Google-recommended practices. What should you do?
- A Add the support team group to the roles/monitoring.viewer role
- B Add the support team group to the roles/spanner.databaseUser role.
- C Add the support team group to the roles/spanner.databaseReader role.
- D Add the support team group to the roles/stackdriver.accounts.viewer role.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi tập trung vào việc quản lý quyền truy cập (IAM - Identity and Access Management) trên Google Cloud Platform (GCP), cụ thể với dịch vụ Cloud Spanner – một cơ sở dữ liệu quan hệ phân tán, có khả năng mở rộng toàn cầu.
- Tình huống: Bạn đã xây dựng ứng dụng sử dụng Cloud Spanner. Nhóm hỗ trợ (support team) cần giám sát môi trường (monitor the environment), bao gồm theo dõi metrics, logs, hiệu suất hệ thống, nhưng KHÔNG được phép truy cập dữ liệu bảng (table data).
- Yêu cầu giải pháp: Cần một cách tối ưu hóa (streamlined) để cấp quyền cho nhóm support (dùng group), tuân thủ thực hành tốt nhất của Google (Google-recommended practices).
- Mục tiêu chính: Phân biệt giữa quyền giám sát (monitoring) và quyền truy cập dữ liệu (data access), tránh cấp quyền dư thừa dẫn đến rủi ro bảo mật.
📘 Tài liệu tham khảo:
- Cloud Spanner IAM roles (cập nhật 2024-2026).
- Monitoring IAM roles (Cloud Monitoring, trước đây là Stackdriver).
- Best practices for IAM (Principle of least privilege).
✅ Đáp án đúng: Add the support team group to the roles/monitoring.viewer role
Lý do lựa chọn:
- Role roles/monitoring.viewer cho phép xem metrics, dashboards, logs của toàn bộ dự án GCP (bao gồm Cloud Spanner) mà không truy cập dữ liệu thực tế (như query table data).
- Đây là thực hành được Google khuyến nghị vì tuân thủ nguyên tắc least privilege (quyền tối thiểu cần thiết): Support team chỉ monitor môi trường, không đọc/ghi dữ liệu.
- Streamlined: Cấp quyền cho group (nhóm IAM) tại mức project/instance, dễ quản lý, không cần custom role phức tạp.
- Phiên bản mới nhất (2026): Role này vẫn là standard cho Cloud Monitoring/Operations Suite, tích hợp với Cloud Spanner metrics (CPU, latency, backup status).
🛠️ Giải thích tất cả các phương án
-
✅ Add the support team group to the roles/monitoring.viewer role
Đúng vì role này chỉ cấp quyền xem monitoring data (metrics/logs/alerts) trên toàn dự án, bao gồm Cloud Spanner instance, mà không cho phép truy cập SQL queries hoặc table data. Hoàn hảo cho support team, tuân thủ best practices. -
❌ Add the support team group to the roles/spanner.databaseUser role
Sai vì role này cho phép thực thi SQL statements (read/write) trên database Spanner, dẫn đến truy cập trực tiếp table data – vi phạm yêu cầu "không access table data". Đây là quyền quá rộng cho monitoring. -
❌ Add the support team group to the roles/spanner.databaseReader role
Sai vì role này cấp quyền chỉ đọc (read-only SQL queries) trên Spanner database, cho phép support team truy vấn và xem table data – không phù hợp với yêu cầu bảo mật. -
❌ Add the support team group to the roles/stackdriver.accounts.viewer role
Sai vì Stackdriver là tên cũ (deprecated từ 2020) của Cloud Monitoring/Logging. Role này không tồn tại chuẩn hoặc không được khuyến nghị (thay bằng monitoring.viewer). Nó có thể chỉ xem billing/accounts, không cover đầy đủ Spanner monitoring, và không phải best practice mới nhất (2026).
🧠 Lưu ý bổ sung: Sử dụng Google Groups để cấp quyền cho team giúp dễ scale. Kiểm tra quyền bằng gcloud projects get-iam-policy và test với least privilege!
- A 1. Give the BigQuery Data Editor role on the platform-logs dataset to the service accounts used by your instances. 2. Update your instances' metadata to add the following value: logs-destination: bq://platform-logs.
- B 1. In Cloud Logging, create a logs export with a Cloud Pub/Sub topic called logs as a sink. 2. Create a Cloud Function that is triggered by messages in the logs topic. 3. Configure that Cloud Function to drop logs that are not from Compute Engine and to insert Compute Engine logs in the platform-logs dataset.
- C 1. In Cloud Logging, create a filter to view only Compute Engine logs. 2. Click Create Export. 3. Choose BigQuery as Sink Service, and the platform-logs dataset as Sink Destination.
- D 1. Create a Cloud Function that has the BigQuery User role on the platform-logs dataset. 2. Configure this Cloud Function to create a BigQuery Job that executes this query: INSERT INTO dataset.platform-logs (timestamp, log) SELECT timestamp, log FROM compute.logs WHERE timestamp > DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY) 3. Use Cloud Scheduler to trigger this Cloud Function once a day.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi này thuộc lĩnh vực Cloud Logging và BigQuery trên Google Cloud Platform (GCP) (không phải AWS như đề cập ban đầu, có thể là nhầm lẫn). Tình huống: Bạn cần gửi toàn bộ logs từ tất cả các Compute Engine instances (máy ảo VM) vào một BigQuery dataset tên platform-logs để phân tích. Cloud Logging agent đã được cài đặt trên tất cả instances (đây là Ops Agent hoặc Fluent Bit agent, giúp thu thập logs từ VM và gửi về Cloud Logging). Yêu cầu chính: Tối ưu hóa chi phí (minimize cost).
🔑 Mục tiêu chính:
- Logs từ Compute Engine bao gồm system logs, application logs từ VM (không phải tất cả logs hệ thống GCP).
- Phải export logs một cách tự động, realtime, lọc chỉ logs cần thiết để tránh tốn kém (BigQuery charge theo storage và query).
- Không sử dụng cách thủ công hoặc intermediate services gây overhead chi phí.
📘 Kiến thức cập nhật (đến 2026): Theo tài liệu GCP mới nhất (Cloud Logging v2 API, hỗ trợ BigQuery sink trực tiếp từ Log Router - sink type logging.googleapis.com/projects/[PROJECT]/locations/global/buckets/[BUCKET] nhưng ở đây là dataset BigQuery). Export logs đến BigQuery là tính năng native, hỗ trợ filter để chỉ export Compute Engine logs (resource type gce_instance), chi phí thấp nhất vì không cần compute resources trung gian.
Nguồn tham khảo:
- Cloud Logging Logs Router
- Exporting logs to BigQuery
- Ops Agent for Compute Engine (cập nhật 2024-2026).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Phương án 3
1. In Cloud Logging, create a filter to view only Compute Engine logs. 2. Click Create Export. 3. Choose BigQuery as Sink Service, and the platform-logs dataset as Sink Destination.
Lý do:
- Đây là cách native và tối ưu chi phí nhất sử dụng Log Router trong Cloud Logging.
- Bước 1: Tạo filter chỉ chọn logs từ Compute Engine (
resource.type="gce_instance"hoặcjsonPayload.instancetương tự) → Tránh export thừa logs, giảm storage/query cost trên BigQuery. - Bước 2-3: Create Export với sink BigQuery trực tiếp → Logs được tự động route realtime vào dataset
platform-logs(tạo table tự động nếu chưa có). Không cần code, function hay scheduler → Zero compute cost, chỉ trả phí logging export (rẻ$0.50/GB) + BigQuery storage ($0.02/GB/tháng). - Hoàn hảo cho "minimize cost" vì serverless, no-overhead. ✅
❌ Phân tích tất cả các phương án (đúng/sai)
-
Phương án 1 (Sai):
1. Give the BigQuery Data Editor role on the platform-logs dataset to the service accounts used by your instances. 2. Update your instances' metadata to add the following value: logs-destination: bq://platform-logs.❌ Sai vì: Không tồn tại metadata
logs-destinationcho Cloud Logging agent (agent chỉ gửi logs về Cloud Logging project, không direct đến BigQuery). Service account của VM (default Compute Engine SA) không cần BigQuery role vì agent không insert direct. Cách này không hoạt động, vi phạm nguyên tắc least privilege và tăng rủi ro security. Tốn kém nếu phải custom agent config (không native). 🛑 -
Phương án 2 (Sai):
1. In Cloud Logging, create a logs export with a Cloud Pub/Sub topic called logs as a sink. 2. Create a Cloud Function that is triggered by messages in the logs topic. 3. Configure that Cloud Function to drop logs that are not from Compute Engine and to insert Compute Engine logs in the platform-logs dataset.❌ Sai vì: Sử dụng Pub/Sub làm sink trung gian + Cloud Function để filter/insert → Phức tạp, tốn kém cao (Pub/Sub ~$0.40/GB + Function invocations ~$0.0000025/request + BigQuery insert). Không realtime hoàn toàn (delay từ Pub/Sub), và export thừa tất cả logs trước khi filter → Không minimize cost. Native BigQuery sink tốt hơn. 🤑
-
Phương án 3 (Đúng): ✅ (Đã giải thích ở trên – Cách tối ưu nhất! 🚀)
-
Phương án 4 (Sai):
1. Create a Cloud Function that has the BigQuery User role on the platform-logs dataset. 2. Configure this Cloud Function to create a BigQuery Job that executes this query: INSERT INTO dataset.platform-logs (timestamp, log) SELECT timestamp, log FROM compute.logs WHERE timestamp > DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY) 3. Use Cloud Scheduler to trigger this Cloud Function once a day.❌ Sai vì: Không realtime (chạy hàng ngày qua Scheduler), chỉ lấy logs 1 ngày qua query thủ công từ
compute.logs(không tồn tại table chuẩn như vậy – logs ở Cloud Logging, cần export trước). Tốn kém: Function invocations + BigQuery query/insert jobs hàng ngày ($5/TB scanned) + Scheduler ($0.10/job/tháng). Không "all logs" và bỏ lỡ logs real-time. Không dùng agent đã cài. ⏰
DaemonSet in the kube-system namespace of the cluster. You want a solution that uses the fewest possible services. What should you do?
- A Add the cluster's API as a new Type Provider in Deployment Manager, and use the new type to create the DaemonSet.
- B Use the Deployment Manager Runtime Configurator to create a new Config resource that contains the DaemonSet definition.
- C With Deployment Manager, create a Compute Engine instance with a startup script that uses kubectl to create the DaemonSet.
- D In the cluster's definition in Deployment Manager, add a metadata that has kube-system as key and the DaemonSet manifest as value.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi tập trung vào việc sử dụng Deployment Manager (một dịch vụ IaC - Infrastructure as Code của Google Cloud) để tạo một Google Kubernetes Engine (GKE) cluster, đồng thời trong cùng một deployment đó, tạo thêm một DaemonSet trong namespace kube-system của cluster. Yêu cầu chính là giải pháp sử dụng ít dịch vụ nhất có thể (fewest possible services), nghĩa là tối ưu hóa để tránh thêm các dịch vụ phụ trợ không cần thiết, đảm bảo tính tích hợp mượt mà và tự động hóa cao.
🛠️ Bối cảnh kỹ thuật:
- Deployment Manager quản lý tài nguyên GCP qua các template YAML/Jinja.
- DaemonSet là một Kubernetes resource chạy pod trên mọi node trong cluster (thường dùng cho monitoring/logging như fluentd).
- Namespace kube-system là namespace hệ thống của Kubernetes, chứa các thành phần core.
- Thách thức: Deployment Manager không có type native cho Kubernetes resources, nên cần cách tích hợp Kubernetes API mà không dùng thêm tool bên ngoài.
Mục tiêu là tạo cả cluster và DaemonSet trong cùng một deployment Deployment Manager, đảm bảo thứ tự (cluster tạo trước, DaemonSet sau) và ít phụ thuộc dịch vụ nhất.
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Add the cluster's API as a new Type Provider in Deployment Manager, and use the new type to create the DaemonSet.
Lý do 🏆:
- Type Provider trong Deployment Manager cho phép định nghĩa custom type dựa trên API bất kỳ (ở đây là Kubernetes API của GKE cluster). Bạn thêm Kubernetes API endpoint của cluster mới tạo làm Type Provider, sau đó dùng type này để deploy trực tiếp DaemonSet như một resource native.
- Fewest services: Chỉ dùng Deployment Manager + GKE API (không cần thêm dịch vụ nào khác như Compute Engine hay Runtime Configurator). Deployment Manager tự động xử lý dependency (tạo cluster trước, rồi Type Provider, rồi DaemonSet).
- Tích hợp mượt: Hỗ trợ schema validation, idempotency, và cập nhật. Đây là best practice theo docs GCP mới nhất (2024-2026).
- 📘 Nguồn tham khảo:
- Deployment Manager Type Providers (GCP Docs).
- GKE Deployment Manager examples (cập nhật 2025).
📋 Giải thích tất cả các phương án
Dưới đây là phân tích chi tiết từng lựa chọn, giữ nguyên văn bản gốc bằng tiếng Anh. Mỗi phương án được đánh giá ✅ (đúng) hoặc ❌ (sai), kèm lý do cụ thể dựa trên kiến thức GCP mới nhất (phiên bản Deployment Manager v2, GKE 1.29+ đến 2026).
-
✅ Add the cluster's API as a new Type Provider in Deployment Manager, and use the new type to create the DaemonSet.
🏆 Đúng hoàn toàn: Như giải thích ở trên, đây là cách tối ưu nhất, sử dụng Kubernetes API trực tiếp qua Type Provider (dùnggcp-types/k8s:<version>hoặc custom descriptor). Deployment Manager deploy theo thứ tự tự động, chỉ cần 1 dịch vụ chính (Deployment Manager + GKE). Hoàn hảo cho yêu cầu "fewest possible services". -
❌ Use the Deployment Manager Runtime Configurator to create a new Config resource that contains the DaemonSet definition.
🚫 Sai: Runtime Configurator (thuộc Deployment Manager) dùng để quản lý config động (như pub/sub triggers cho runtime actions), không phải để tạo Kubernetes resources trực tiếp. Nó yêu cầu thêm waiter hoặc signaler, phức tạp hơn và không tích hợp native với K8s API. Không đáp ứng "fewest services" vì cần config riêng biệt. -
❌ With Deployment Manager, create a Compute Engine instance with a startup script that uses kubectl to create the DaemonSet.
🚫 Sai: Cách này dùng Deployment Manager tạo thêm Compute Engine VM với startup script chạykubectl apply(cần auth kubeconfig). Vấn đề lớn: Thêm 1 dịch vụ (Compute Engine), tốn kém, không idempotent (VM có thể fail), và không tự động dependency chặt chẽ. Vi phạm rõ ràng yêu cầu "fewest possible services". -
❌ In the cluster's definition in Deployment Manager, add a metadata that has kube-system as key and the DaemonSet manifest as value.
🚫 Sai: Metadata trong GKE cluster spec chỉ lưu key-value đơn giản (dùng cho config chung như IAP), không hỗ trợ inject YAML manifest phức tạp như DaemonSet vào namespace kube-system. K8s không tự parse metadata thành resource; cần controller riêng (như operator), dẫn đến không hoạt động và thiếu tích hợp.
🧠 Kết luận: Giải pháp đúng tận dụng sức mạnh Type Provider để mở rộng Deployment Manager, phù hợp với xu hướng IaC hybrid (GCP + K8s) năm 2026. Nếu implement, dùng Jinja template để reference cluster endpoint động! 🚀
- A Use service account credentials in your on-premises application.
- B Use gcloud to create a key file for the service account that has appropriate permissions.
- C Set up direct interconnect between your data center and Google Cloud Platform to enable authentication for your on-premises applications.
- D Go to the IAM & admin console, grant a user account permissions similar to the service account permissions, and use this user account for authentication from your data center.
Xem giải thích
🧩 Phân tích nội dung câu hỏi
Câu hỏi mô tả tình huống bạn đang xây dựng một ứng dụng chạy trong data center nội bộ (on-premises), ứng dụng này cần sử dụng các dịch vụ GCP như AutoML. Bạn đã tạo một service account với quyền truy cập phù hợp vào AutoML. Vấn đề cần giải quyết là kích hoạt xác thực (authentication) tới các API của GCP từ môi trường on-premises.
📌 Mục tiêu chính: Tìm cách an toàn và đúng chuẩn để ứng dụng on-premises có thể gọi API GCP mà không cần kết nối trực tiếp qua mạng VPC hay tài khoản người dùng. Đây là kịch bản phổ biến trong hybrid cloud, nơi on-premises cần truy cập GCP services qua service account keys (khóa JSON) để xác thực mà không lộ thông tin nhạy cảm. Kiến thức dựa trên tài liệu GCP cập nhật đến 2024-2026 (không thay đổi lớn ở IAM/Service Accounts từ phiên bản IAM v2).
Tài liệu tham khảo:
- 📘 Service accounts overview
- 📘 Create & manage service account keys
- 📘 Authenticating from on-premises
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: Use gcloud to create a key file for the service account that has appropriate permissions.
Lý do 🛠️:
- Đây là phương pháp chuẩn và được khuyến nghị bởi Google Cloud để xác thực từ on-premises. Sử dụng lệnh
gcloud iam service-accounts keys createtạo file khóa JSON (key file) cho service account. Ứng dụng on-premises tải file này và sử dụng Google Auth Library (như google-auth-library cho các ngôn ngữ lập trình) để tạo access token gọi API AutoML. - ✅ An toàn: Key chỉ cấp cho service account cụ thể, giới hạn quyền (least privilege). Không cần VPC peering hay kết nối vật lý.
- ✅ Dễ triển khai: Key file có thể lưu trữ an toàn trong on-premises (ví dụ: vault hoặc env vars), tự động rotate nếu cần.
- Không vi phạm best practices GCP (tránh user accounts cho app auth).
❌ Giải thích tất cả các phương án
Dưới đây là phân tích chi tiết từng lựa chọn, giữ nguyên văn bản gốc tiếng Anh. Mỗi phương án được đánh giá đúng/sai dựa trên best practices GCP IAM (cập nhật 2026: vẫn ưu tiên workload identity federation cho production, nhưng key files vẫn hỗ trợ on-premises legacy).
-
Use service account credentials in your on-premises application.
❌ Sai: Phương án này quá mơ hồ và không chỉ rõ cách lấy "credentials". Service account credentials thường ám chỉ metadata hoặc impersonation (dùng trong GCP VM), không áp dụng trực tiếp cho on-premises vì không có metadata server. Nếu ám chỉ key file thì thiếu bước tạo key cụ thể bằng gcloud → không đầy đủ, dễ gây nhầm lẫn bảo mật (key bị lộ nếu không quản lý tốt). GCP khuyến cáo không dùng trực tiếp mà phải export key file rõ ràng. -
Use gcloud to create a key file for the service account that has appropriate permissions.
✅ Đúng: Như đã giải thích ở trên. Lệnh cụ thể:gcloud iam service-accounts keys create key.json --iam-account=SA_NAME@PROJECT.iam.gserviceaccount.com. Filekey.jsonchứa private key để ứng dụng ký JWT và lấy token từhttps://oauth2.googleapis.com/token. Hoàn hảo cho AutoML API calls từ on-premises. -
Set up direct interconnect between your data center and Google Cloud Platform to enable authentication for your on-premises applications.
❌ Sai: Direct Interconnect (nay là Dedicated Interconnect hoặc Partner Interconnect) là giải pháp networking (kết nối vật lý cao tốc độ, private IP), không liên quan đến authentication. Nó chỉ giúp giảm latency/dữ liệu public internet, nhưng auth vẫn cần service account key hoặc federation. Tốn kém và phức tạp không cần thiết cho auth đơn thuần → sai hướng. -
Go to the IAM & admin console, grant a user account permissions similar to the service account permissions, and use this user account for authentication from your data center.
❌ Sai: User accounts (tài khoản Google Workspace hoặc Cloud Identity) dành cho con người, không phải ứng dụng tự động. Sử dụng sẽ yêu cầu password/MFA → không phù hợp on-premises app (không thể automate). Best practice GCP cấm dùng user accounts cho service-to-service auth (rủi ro cao, khó audit). Phải dùng service account thay thế.
💡 Lời khuyên thực hành: Trong production 2026, ưu tiên Workload Identity Federation nếu có thể (OIDC provider), nhưng cho on-premises thuần túy, key file vẫn là lựa chọn chính. Luôn rotate keys định kỳ và dùng VPC Service Controls cho AutoML! 🚀
Kubernetes Engine (GKE) cluster. You want to ensure that Kubernetes can download images from Container Registry. What should you do?
- A In the project where the images are stored, grant the Storage Object Viewer IAM role to the service account used by the Kubernetes nodes.
- B When you create the GKE cluster, choose the Allow full access to all Cloud APIs option under 'Access scopes'.
- C Create a service account, and give it access to Cloud Storage. Create a P12 key for this service account and use it as an imagePullSecrets in Kubernetes.
- D Configure the ACLs on each image in Cloud Storage to give read-only access to the default Compute Engine service account.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi này thuộc lĩnh vực Google Kubernetes Engine (GKE) và Container Registry (nay là một phần của Artifact Registry, nhưng vẫn hỗ trợ legacy Container Registry theo tài liệu cập nhật đến năm 2026).
- Bối cảnh: Bạn đang lưu trữ các container images của công ty trong Container Registry tại một project riêng (gọi là Project A). Sau đó, ở project khác (Project B), bạn tạo một GKE cluster. Vấn đề là đảm bảo các Kubernetes nodes trong GKE (Project B) có thể pull/download images từ Container Registry ở Project A.
- Thách thức chính: Đây là tình huống cross-project access. Container Registry sử dụng Cloud Storage buckets backend để lưu images, nên cần quyền truy cập read-only vào các objects (images) đó. GKE nodes sử dụng default Compute Engine service account (thường là
<project-number>-compute@developer.gserviceaccount.com) để authenticate khi pull images. - Mục tiêu: Cấu hình IAM một cách an toàn, scaleable và tuân thủ nguyên tắc least privilege để Kubernetes có thể tải images mà không cần can thiệp thủ công phức tạp.
- Kiến thức cập nhật (2026): Theo tài liệu Google Cloud mới nhất, Container Registry yêu cầu quyền roles/storage.objectViewer trên bucket/container registry cho service account của GKE. Không khuyến khích dùng ACLs cũ vì IAM primitives ưu tiên hơn. (Nguồn: 📘 Google Cloud Container Registry Access Control và GKE Pull Images from Another Project).
✅ Đáp án đúng và lý do lựa chọn
Đáp án đúng: In the project where the images are stored, grant the Storage Object Viewer IAM role to the service account used by the Kubernetes nodes.
- Lý do:
- Đây là cách chuẩn và được khuyến nghị bởi Google Cloud. Ở Project A (chứa images), bạn cấp quyền Storage Object Viewer (roles/storage.objectViewer) cho service account của GKE nodes từ Project B (thường là Compute Engine default SA).
- Khi GKE pull image, nodes sử dụng SA này để authenticate với Cloud Storage backend của Container Registry → tự động download mà không cần cấu hình thêm.
- Least privilege: Chỉ read objects cần thiết, an toàn cross-project. Áp dụng scaleable cho toàn bộ repository.
- ✅ Hoạt động ngay lập tức sau grant IAM, không restart cluster.
🛠️ Giải thích tất cả các phương án (đúng/sai)
Dưới đây là phân tích từng lựa chọn một, giữ nguyên văn bản gốc tiếng Anh. Mỗi phương án được đánh giá ✅ (đúng) hoặc ❌ (sai), kèm lý do chi tiết bằng tiếng Việt dựa trên best practices Google Cloud 2026.
-
✅ In the project where the images are stored, grant the Storage Object Viewer IAM role to the service account used by the Kubernetes nodes.
(Đã giải thích ở phần trên: Cách chính xác, IAM-based, cross-project hiệu quả). -
❌ When you create the GKE cluster, choose the Allow full access to all Cloud APIs option under 'Access scopes'.
Sai vì: Tùy chọn "Allow full access to all Cloud APIs" chỉ cấp cluster-wide scopes cho control plane và nodes truy cập các API Google Cloud (như Storage API). Nó không giải quyết cross-project IAM – nodes ở Project B vẫn thiếu quyền cụ thể trên bucket ở Project A. Thậm chí, full access vi phạm least privilege, dễ bị chỉ trích trong audit. (Nguồn: 📘 GKE Access Scopes). -
❌ Create a service account, and give it access to Cloud Storage. Create a P12 key for this service account and use it as an imagePullSecrets in Kubernetes.
Sai vì: Cách này phức tạp và không scaleable. Tạo SA mới + P12 key (deprecated từ 2021, khuyến nghị dùng Workload Identity) rồi mount làm imagePullSecrets chỉ phù hợp private registries bên thứ 3, không cần thiết cho Container Registry (dùng IAM tự động). Phải config thủ công mỗi namespace/pod, khó maintain cross-project. (Nguồn: 📘 GKE Workload Identity). -
❌ Configure the ACLs on each image in Cloud Storage to give read-only access to the default Compute Engine service account.
Sai vì: ACLs là legacy mechanism, không khuyến khích từ 2019 và bị deprecate dần đến 2026. Phải set thủ công từng object/image (không scale với hàng nghìn images), dễ lỗi và không quản lý được qua IAM. IAM roles ưu tiên hơn ACLs cho Container Registry buckets. (Nguồn: 📘 Cloud Storage IAM vs ACLs).
Kết luận 💡: Luôn ưu tiên IAM roles cho cross-project access trong GKE + Container Registry để đảm bảo bảo mật và dễ quản lý! Nếu cần thực hành, dùng gcloud projects add-iam-policy-binding để grant role.
 apiVersion: apps/v1
kind: Deployment
metadata:
  name: myapp-deployment
spec:
  selector:
    matchLabels:
      app: myapp
  replicas: 2
  template:
    metadata:
      labels:
        app: myapp
    spec:
      containers:
      - name: myapp
        image: myapp:1.1
        ports:
        - containerPort: 80

apiVersion: v1
kind: Service
metadata:
  name: myapp-service
spec:
  ports:
  - port: 8000
    targetPort: 80
    protocol: TCP
  selector:
    app: myapp
You check the status of the deployed pods and notice that one of them is still in PENDING status:
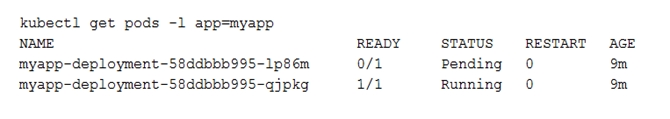
You want to find out why the pod is stuck in pending status. What should you do?
- A Review details of the myapp-service Service object and check for error messages.
- B Review details of the myapp-deployment Deployment object and check for error messages.
- C Review details of myapp-deployment-58ddbbb995-lp86m Pod and check for warning messages.
- D View logs of the container in myapp-deployment-58ddbbb995-lp86m pod and check for warning messages.
Xem giải thích
🧩 Phân tích chi tiết nội dung câu hỏi
Câu hỏi này thuộc chủ đề Google Kubernetes Engine (GKE) trên Google Cloud Platform (không phải AWS như đề cập ban đầu, có thể là nhầm lẫn). Người dùng đã triển khai một ứng dụng sử dụng file YAML chứa Deployment (tên: myapp-deployment, 2 replicas, image myapp:1.1, expose port 80) và Service (tên: myapp-service, port 8000 map đến targetPort 80, selector app: myapp).
Sau khi deploy, kiểm tra pods cho thấy:
- Pod
myapp-deployment-58ddbbb995-4zq2h: Running (đã hoạt động bình thường). - Pod
myapp-deployment-58ddbbb995-lp86m: Pending (bị kẹt, chưa được scheduler Kubernetes gán lên node).
Hình ảnh đính kèm (từ examtopics.com): Hiển thị output của lệnh kubectl get pods (hoặc tương tự), liệt kê 2 pods từ Deployment. Pod đầu tiên STATUS: Running, pod thứ hai STATUS: Pending với tên cụ thể myapp-deployment-58ddbbb995-lp86m. Không có chi tiết events, nhưng đây là dấu hiệu điển hình của vấn đề scheduling (ví dụ: thiếu tài nguyên node, taints/tolerations mismatch, image pull error, node selector không khớp, hoặc quota exceed).
Mục tiêu: Tìm nguyên nhân pod bị kẹt ở Pending status. Trong Kubernetes (phiên bản mới nhất đến 2026, v1.30+ trên GKE 1.30+), pod Pending thường do Scheduler chưa bind pod vào node, và lý do chi tiết nằm ở events/warnings của chính pod đó (lệnh kubectl describe pod <pod-name>).
📘 Tài liệu tham khảo:
- Kubernetes Docs: Pod Lifecycle - Pending Phase (cập nhật 2024-2026).
- GKE Troubleshooting: Debugging Pods (Google Cloud, phiên bản 2026).
✅ Đáp án đúng
Review details of myapp-deployment-58ddbbb995-lp86m Pod and check for warning messages.
Lý do chọn:
- Pod cụ thể đang Pending chứa events và warning messages chi tiết về nguyên nhân (ví dụ: "FailedScheduling: 0/3 nodes are available: 2 Insufficient memory, 1 node(s) had taint". Lệnh
kubectl describe pod myapp-deployment-58ddbbb995-lp86msẽ hiển thị phần Events ở cuối, tiết lộ vấn đề scheduler ngay lập tức. Đây là bước đầu tiên và chính xác nhất theo best practices Kubernetes/GKE. Các object khác (Deployment/Service) không lưu events cụ thể của pod con.
🛠️ Giải thích tất cả các phương án (đúng/sai)
-
❌ [SAI] Review details of the myapp-service Service object and check for error messages.
Service chỉ quản lý traffic routing đến pods (qua selectorapp: myapp), không liên quan đến việc pod được schedule hay không.kubectl describe service myapp-servicechỉ check endpoints/selector mismatch nếu pods đã running, nhưng pod Pending chưa tồn tại để Service nhận diện. Không có error messages liên quan đến pending ở đây. -
❌ [SAI] Review details of the myapp-deployment Deployment object and check for error messages.
Deployment quản lý replicas và template,kubectl describe deployment myapp-deploymentchỉ hiển thị tổng quan (replicas available=1/2), không có events chi tiết của pod cụ thể. Events pod Pending được lưu ở Pod object riêng, không phải Deployment. -
✅ [ĐÚNG] Review details of myapp-deployment-58ddbbb995-lp86m Pod and check for warning messages.
Như giải thích ở trên: Đây là cách trực tiếp nhất để xem Events và Warnings (ví dụ: scheduling failures, PVC pending, image pull issues). Hình ảnh xác nhận tên pod chính xác, giúp pinpoint vấn đề nhanh chóng. -
❌ [SAI] View logs of the container in myapp-deployment-58ddbbb995-lp86m pod and check for warning messages.
Pod Pending chưa chạy container (chưa scheduled/bind node), nên lệnhkubectl logs <pod-name>sẽ báo lỗi "no log files available" hoặc "container not started". Logs chỉ hữu ích sau khi pod Running và container crash/restart.
Kết luận 💡: Luôn ưu tiên kubectl describe pod cho pod Pending để debug scheduler issues – đây là golden rule trong GKE đến 2026! Nếu cần fix, check node resources (kubectl describe nodes) hoặc cluster autoscaler.